+ + # 2. Listening to gravitational waves + """ + ) + return + + +@app.cell(hide_code=True) +def _(mo): + mo.md(r"""Here, we'll look at and listen to the "expected signal" from the merger of a black-hole binary like the one measured in GW150914. This signal was created from a simulation of two black holes spiraling in toward each other.""") + return + + +@app.cell +def _(InterpolatedUnivariateSpline, derivative, fade, io, np, requests): + NR_file_path = "https://raw.githubusercontent.com/chengj7/MatchedFiltering/refs/heads/binder/content/data/NR_GW150914.txt" + NR_response = requests.get(NR_file_path) + #NR_data = np.load(BytesIO(NR_response.content)) + + + # Load the raw NR data produced by the SXS collaboration + nr_complex = np.exp(0.1j*np.pi) * np.loadtxt(io.StringIO(NR_response.text)).view(dtype=complex)[:, 0] + nr = fade(nr_complex.real) + + # # Load LIGO's official template (which isn't as good) + # with h5py.File('data/GW150914_4_template.hdf5') as f: + # nr = np.roll(fade(f['template'][0]), 1807) / 437.666 + + # Set up the time and sampling-frequency information for this signal + sampling_rate = 4096.0 # Hz + dt = 1/sampling_rate + t = np.arange(len(nr)) / sampling_rate + + # Get the time-domain frequency using the complex data + nr_phase = np.unwrap(np.angle(nr_complex)) + nr_angular_frequency = derivative(nr_phase, t) + nr_frequency_interpolator = InterpolatedUnivariateSpline(t, nr_angular_frequency/(2*np.pi)) + + # Now Fourier transform the data, and get the corresponding frequencies + nrtilde = dt * np.fft.rfft(nr) + frequencies = np.fft.rfftfreq(len(nr), dt) + return ( + dt, + frequencies, + nr, + nr_frequency_interpolator, + nrtilde, + sampling_rate, + t, + ) + + +@app.cell(hide_code=True) +def _(mo): + mo.md( + r""" + We can plot the signal in both the time and frequency domains, and even play the signal over headphones. + + ***CAUTION:*** If you can hear the long, deep inspiral at the beginning of the signal, then the merger may be very loud. Be prepared to take your headphones away from your ears, or to turn down the volume, around the 16 second mark. + """ + ) + return + + +@app.cell +def _(mo, np, plt): + def plot_td_and_fd_mpl(t, hprime, f, htildeprime, h=None, htilde=None): + print('Contrast: {0:.4f}'.format(np.max(np.abs(hprime)) / np.sqrt(np.mean(np.abs(hprime)**2)))) + sampling_rate = 1.0/(t[1]-t[0]) + plt.close('all') + fig, (ax1, ax2) = plt.subplots(1, 2) + if h is not None: + ax1.plot(t, h, label='Raw data') + ax1.plot(t, hprime, label='Filtered data') + ax1.legend(loc='lower left'); + else: + ax1.plot(t, hprime) + ax1.set_xlabel('Time (seconds)') + ax1.set_ylabel('Detector strain $h$ (dimensionless)') + ax1.set_xlim(xmax=t[-1]) + ax1.set_ylim(1.1*np.min(hprime), 1.1*np.max(hprime)) + ax1.set_title('Time domain') + ax1.grid() + if htilde is not None: + ax2.loglog(f, abs(htilde), label='Raw data') + ax2.loglog(f, abs(htildeprime), label='Filtered data') + ax2.legend(loc='lower left'); + else: + ax2.loglog(f, abs(htildeprime)) + ax2.set_xlabel('Frequency (Hz)') + ax2.set_ylabel(r'Detector strain Fourier transform $\tilde{h}$ (seconds)') + ax2.set_xlim(1, sampling_rate/2) + ax2.set_title('Frequency domain') + ax2.grid() + fig.tight_layout() + audio = mo.audio(src=hprime, rate=int(sampling_rate)) + return fig, (ax1, ax2), audio + return (plot_td_and_fd_mpl,) + + +@app.cell +def _(fade, np, plot_td_and_fd_mpl): + def filter_and_plot_mpl( + h, t, htilde, sampling_rate, sliders, notch_filters, equalizer_power, notch_filter_power, + frequencies, frequency_bin_upper_ends + ): + import marimo as mo + + # Get levels from sliders + levels = np.ones_like(frequencies) + if equalizer_power.value == "On": + slider_values = [s.value for s in sliders] + for i, f in enumerate(frequency_bin_upper_ends): + if i==0: + f_last = 0.0 + levels[(frequencies >= f_last) & (frequencies < f)] = 10**(slider_values[i]/20.0) + f_last = f + + # Get notch filters (if any) + if notch_filter_power.value == "On": + for _notch_filter in notch_filters: + f_begin, f_end, f_bool = [child.value for child in _notch_filter] + if (f_bool is True) and (f_begin
+ + # 3. Listening to detector data + """ + ) + return + + +@app.cell(hide_code=True) +def _(mo): + mo.md(r"""The LIGO collaboration claimed that the signal we listened to above (or one very much like it) is found in their detector data from September 14, 2015. [We have that data](https://losc.ligo.org/about/), and we can look for the signal ourselves. First, we'll load the data. The following cell will give us the actual raw data that came out of the detector in Hanford, Washington.""") + return + + +@app.cell +def _(fade, h5py, io, requests): + Hanford_file_path = "https://raw.githubusercontent.com/chengj7/MatchedFiltering/refs/heads/binder/content/data/H-H1_LOSC_4_V1-1126259446-32.hdf5" + Hanford_response = requests.get(Hanford_file_path) + + Hanford_file_bytes = io.BytesIO(Hanford_response.content) + + # Load the raw data from LIGO Hanford + with h5py.File(Hanford_file_bytes, 'r') as f1: + h = f1['strain/Strain'][:] # Time of event is 16.4 + + # We always want this to turn and off slowly: + h = fade(h) + return (h,) + + +@app.cell(hide_code=True) +def _(mo): + mo.md(r"""We now have a data set named `h`, which represents the strain measured by the detector. We also want to know the times associated with each data point, and a few useful features of that data set:""") + return + + +@app.cell +def _(dt, h, np): + # Now Fourier transform the data, and get the corresponding frequencies + htilde1 = dt * np.fft.rfft(h) + frequencies1 = np.fft.rfftfreq(len(h), dt) + return (htilde1,) + + +@app.cell(hide_code=True) +def _(mo): + mo.md(r"""Now, we're ready to look at and listen to the raw data containing the GW150914 event. First we'll plot the data as a function of time, then we'll plot (the magnitude of) the Fourier transform as a function of frequency. Finally, we'll also be able to listen to the signal. Remember to be careful of the volume.""") + return + + +@app.cell +def _(frequencies, h, htilde1, plot_td_and_fd_mpl, plt, t): + _fig, (_ax1, _ax2), _audio = plot_td_and_fd_mpl(t, h, frequencies, htilde1); + plt.show() + _audio + return + + +@app.cell(hide_code=True) +def _(mo): + mo.md( + r""" + There are controls below the plots that let you zoom in and pan around on the plots. Take a moment to explore the plots and think about these questions: + + + ## Questions + * What happened? Why is this signal nothing at all like the pure gravitational wave we saw above? + * Can you see the signal in the plots? + * Can you hear the signal? + * What are the sources of noise here? + * The raw data sounds generally pretty high-pitched. But looking in the frequency domain, we see that most of the signal is at very low frequencies. Why doesn't the raw data sound low-pitched? + """ + ) + return + + +@app.cell(hide_code=True) +def _(mo): + mo.md( + r""" +
+ + # 4. Digging signal out of noise manually + """ + ) + return + + +@app.cell(hide_code=True) +def _(mo): + mo.md( + r""" + LIGO has a lot of noise. This is entirely expected when dealing with such a sensitive apparatus, but it does swamp the signal. The key to LIGO's success is that the noise is pretty steady (or technically, "stationary"), and the noise is largest at frequencies that aren't the most interesting. We can recover the interesting part of the signal by decreasing the size of the noise. We will do this using a "graphic equalizer". + + A graphic equalizer divides the signal into frequency bands, allows you to adjust the volume in each band, and then combines the signal back into a time-domain signal. You may have seen graphic equalizers in old or high-end stereos: + +
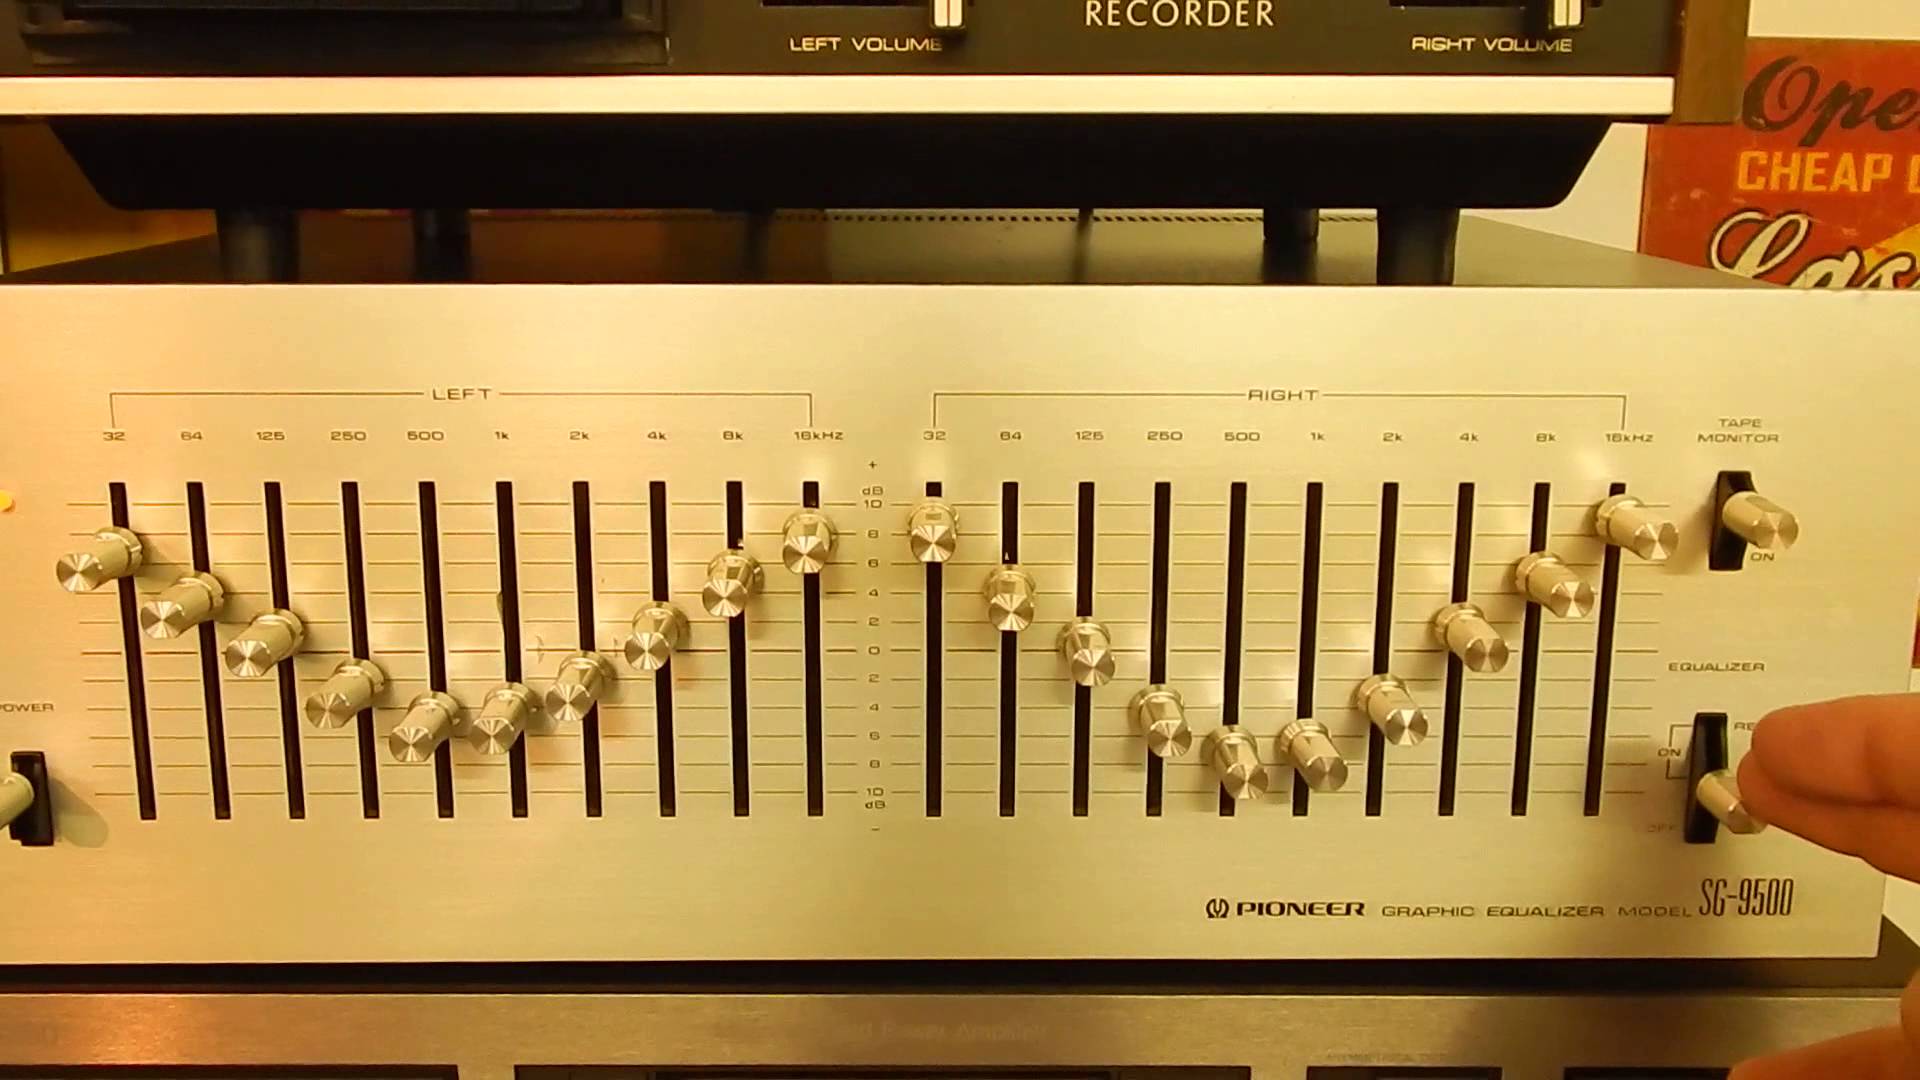 +
+ Nowadays, you might see "bass" and "treble" (and maybe even "mid") controls, which do the same thing, but break the signal down into fewer frequency bands.
+
+ We're going to do the same thing, but without the old-timey hardware. The cell below sets up a graphic equalizer, then produces the "equalized" data for you to look at and listen to. Mess around with the settings, then press "Recalculate" to see how well you can pick out the signal we're looking for.
+ """
+ )
+ return
+
+
+@app.cell
+def _(mo, np, sampling_rate):
+ #setup
+ log2_sampling_rate = int(np.log2(sampling_rate/2))
+ frequency_bin_upper_ends = np.logspace(3, log2_sampling_rate, num=2*(log2_sampling_rate-3)+1, base=2)
+
+ #equalizer power radio button
+ equalizer_power = mo.ui.radio(options=['On','Off'], value='On', label='equalizer')
+
+ #equalizer sliders
+ equalizer_sliders = mo.ui.array([
+ mo.ui.slider(
+ start=-200.0, stop=200.0, step=0.5, value=0.0,
+ orientation="vertical", show_value=True,
+ label=str(int(_freq)),
+ )
+ for _freq in frequency_bin_upper_ends
+ ])
+ equal_sliders_hstack = mo.hstack(equalizer_sliders.elements, widths="equal", gap=0)
+ equalizer_stack = mo.hstack([equalizer_power, equal_sliders_hstack], align='center')
+ return (
+ equalizer_power,
+ equalizer_sliders,
+ equalizer_stack,
+ frequency_bin_upper_ends,
+ )
+
+
+@app.cell
+def _(mo):
+ get_filter_count, set_filter_count = mo.state(0)
+
+ #add buttons
+ add_notch_filter_button = mo.ui.button(
+ label="Add notch filter",
+ on_click=lambda _: set_filter_count(lambda n: n + 1),
+ )
+ notch_filter_power = mo.ui.radio(
+ options=["On", "Off"], value="On", label="Notch Filters"
+ )
+ return add_notch_filter_button, get_filter_count, notch_filter_power
+
+
+@app.cell
+def _(
+ add_notch_filter_button,
+ equalizer_stack,
+ get_filter_count,
+ mo,
+ notch_filter_power,
+):
+ notch_filter_list = mo.ui.array([
+ mo.ui.array([
+ mo.ui.number(value=0.0, label="Begin"),
+ mo.ui.number(value=0.0, label="End"),
+ mo.ui.checkbox(label="Use this filter", value=True),
+ ])
+ for _ in range(get_filter_count())
+ ])
+
+ notch_filters = mo.hstack(
+ [notch_filter_power,
+ mo.vstack([
+ mo.vstack(
+ [mo.hstack(row.elements, justify="space-around")
+ for row in notch_filter_list.elements]
+ ),
+ add_notch_filter_button,
+ ],
+ align="center",
+ ),
+ ],
+ align="center",
+ justify="space-around",
+ gap=1,
+ )
+ mo.vstack([equalizer_stack, notch_filters], align='center')
+ return (notch_filter_list,)
+
+
+@app.cell
+def _(
+ equalizer_power,
+ equalizer_sliders,
+ filter_and_plot_mpl,
+ frequencies,
+ frequency_bin_upper_ends,
+ h,
+ htilde1,
+ notch_filter_list,
+ notch_filter_power,
+ plt,
+ sampling_rate,
+ t,
+):
+ _fig, (_ax1, _ax2), _audio = filter_and_plot_mpl(
+ h, t, htilde1, sampling_rate, equalizer_sliders, notch_filter_list, equalizer_power, notch_filter_power,
+ frequencies, frequency_bin_upper_ends
+ )
+ plt.show()
+ _audio
+ return
+
+
+@app.cell(hide_code=True)
+def _(mo):
+ mo.md(
+ r"""
+ Spend some time playing around with the equalizer to pull out the signal. (Hint: the low and high frequencies are where most of the noise is, and where less of the signal is.)
+
+ You can also add some notch filters to eliminate sharp spikes in the frequency-domain data, if you think they're more like noise than signal. A notch filter is like another equalizer slider, except that you get to control where its frequency band begins and ends, and it sets everything in that band as low as it can go.
+
+ The signal you're looking for peaks near the middle of the data (around $t=16.4\, \mathrm{sec}$).
+
+
+ ## Questions
+ * Can you adjust the filters so that you can see the peak amplitude in the time domain? What does it look like when you zoom in? Can you hear it?
+ * If you leave the $45\,\mathrm{Hz}$ band in the data, you see (and hear) big slow oscillations in the time-domain amplitude that are *much* slower than $45\,\mathrm{Hz}$. Can you explain where these come from, and why they oscillate like that?
+ * How does the largest data point of your filtered data (in the time domain) compare to the largest point in the raw data? Why is this?
+ * With good settings, you should be able to see a large spike right in the middle of the data. But there are other spikes, too. How is the middle spike different from the others?
+ """
+ )
+ return
+
+
+@app.cell(hide_code=True)
+def _(mo):
+ mo.md(
+ r"""
+
+ # 5. Digging signal out of noise automatically + """ + ) + return + + +@app.cell(hide_code=True) +def _(mo): + mo.md( + r""" + There are several ways we could improve the crude filtering we did above with our "equalizer". We'll try two improvements in this section, and more in the following sections. + + First, we could throw in more sliders to adjust for more precise equalization. In fact, the only natural number of sliders is one for every frequency bin in the Fourier transform. But there are already so many sliders for us to adjust that it gets tiring; we'd never be able to manually adjust them all. Plus, we want something automatic that will work in every case. Second, therefore, we can adjust the sliders automatically. Roughly speaking, at frequencies with a lot of noise, we want to filter out a lot of the signal; at frequencies with little noise, we don't want to filter much. + + The first step is to measure the noise as a function of frequency. We already know that the signal is very small during most of our data, so we could define the noise at a particular frequency to just be the magnitude of the Fourier transform of the data. But noise is random, and we've only taken a small sample of this random process, so we'd like to average the spectrum. It turns out that a good way to do this is to split the data into chunks, measure the noise in each chunk, and then average the results — or more precisely the root mean square (RMS). There are some additional tricks to deal smooth out the splitting process, and make sure we use all the data without overcounting some, etc. All these tricks are dealt with in what is called "Welch's method". + """ + ) + return + + +@app.cell +def _(InterpolatedUnivariateSpline, h, np, sampling_rate, scipy): + # Set how many chunks we want to split up the data into. We want to balance the need + # for resolving sharp features in the noise (which would suggest using a small number) + # against averaging enough to reduce the variance (which suggests using a large number). + _number_of_chunks = 8 + + # We want our chunks to have sizes that are powers of 2, which speeds up the Fourier + # transforms involved, but we also want about the right number of chunks. This line + # gives us both, because `int` rounds to the nearest integer. + _points_per_chunk = 2**int(np.log2(len(h)/_number_of_chunks)) + + # Now, we can use Welch's method to automatically estimate the noise spectral density. + # The shenanigans we pull with log2 ensures that the chunks are sized to be a power + # of 2, which speeds up the Fourier transforms involved, but also gives us + # approximately the right number of chunks. + f_noise, _noise_welch = scipy.signal.welch(h, sampling_rate, nperseg=_points_per_chunk) + + # Now we just deal with a little normalization weirdness to define the noise spectral density + noise_spectral_density = np.sqrt(2 * len(h) * _noise_welch / sampling_rate) + + # We'll also need to interpolate onto a finer set of frequencies + noise_spectral_density_interpolator = InterpolatedUnivariateSpline(f_noise,noise_spectral_density) + return f_noise, noise_spectral_density, noise_spectral_density_interpolator + + +@app.cell(hide_code=True) +def _(mo): + mo.md(r"""We can compare our raw data to the estimated noise spectrum:""") + return + + +@app.cell +def _( + f_noise, + frequencies, + htilde1, + noise_spectral_density, + np, + plt, + sampling_rate, +): + plt.close() + plt.loglog(frequencies, np.abs(htilde1), label='Raw data') + plt.loglog(f_noise, noise_spectral_density, label='Noise estimate') + plt.xlim(1, 0.6*sampling_rate) + plt.xlabel('Frequency (Hertz)') + plt.ylabel('Noise spectrum and strain Fourier transform (seconds)') + plt.grid() + plt.legend(); + plt.show() + return + + +@app.cell(hide_code=True) +def _(mo): + mo.md( + r""" + If you zoom in, you can see that our estimated noise spectrum is substantially smoother than the raw data, as we hoped. It also emphasizes spikes because we used the RMS instead of just the simple mean. + + So now that we've estimated the noise, we can use it to automatically "equalize" the raw data. Remember that where the noise is large we want a lot of filtering, and where the noise is small we want little filtering. So we just divide the raw data by the noise estimate: + """ + ) + return + + +@app.cell +def _( + fade, + frequencies, + h, + htilde1, + noise_spectral_density_interpolator, + np, + plot_td_and_fd_mpl, + plt, + sampling_rate, + t, +): + # We simply divide htilde by the noise estimate to "equalize" the data in the frequency domain + htilde_equalized = htilde1 / noise_spectral_density_interpolator(frequencies) + + # Now we transform back to the time domain, and smoothly fade on and off to get rid of loud clicks + h_equalized = fade(sampling_rate * np.fft.irfft(htilde_equalized)) + + # Finally we can plot and listen to the data + _fig, (_ax1, _ax2), _audio = plot_td_and_fd_mpl(t, h_equalized, frequencies, htilde_equalized, h=h, htilde=1e21*htilde1); + plt.show() + _audio + return + + +@app.cell(hide_code=True) +def _(mo): + mo.md( + r""" + Unfortunately, this isn't nearly as good as what we could achieve manually using the graphic equalizer above. If you zoom in, you might be able to convince yourself that the signal is there, and you should be able to hear a little blip at the right time. But unless you knew it was there, you'd have a hard time convincing yourself. Looking at the frequency-domain plot, we see why: There's still a lot of noise at the very high and low frequencies that are much smaller, but not gone. Also, the spikes have not entirely gone away. If you look back at our noise estimate around those spikes, you see that the estimate smears them out. So evidently our way of estimating the noise is not good for very sharp features. + + We can solve each of these problems, however. We'll solve the first by removing the high- and low-frequency components even more than the "equalization" did. We'll solve the second by removing those lines with notch filters before "equalizing" the data. + + The first step is to create notch filters for the spikes we see in the input spectrum. This time, we'll do a slightly better job using smooth notches, instead of the sharp square notches we used above. Here we list each notch (beginning and ending frequencies) and something related to the depth of the notch. This may not seem very automatic, but these spikes are fairly constant, so we can just list them once and use the same list forever. In fact, that's what [LIGO does](https://journals.aps.org/prd/abstract/10.1103/PhysRevD.97.082002). + """ + ) + return + + +@app.cell +def _( + dt, + fade, + frequencies, + h, + notch_data, + np, + plot_td_and_fd_mpl, + plt, + sampling_rate, + t, +): + notch_locations_and_sizes = [ + (35.1, 37.1, 0.25), (35.7, 36., 0.8), (36.6, 36.8, 1.3), (40.9, 41.0, 2), # Gremlins + (59.9, 60.1, 4), (119.9, 120.1, 3), (179.9, 180.1, 4), # Line noise + (299.47, 299.7, 2), (303.2, 303.35, 2), (310., 327., 0.25), (331.7, 332.2, 2), # Violin modes + (500.5, 503.1, 1.0), (504.7, 504.9, 1.5), (507.0, 508.7, 1.5), # Violin modes + (991.2, 992.8, 4), (993.7, 997.0, 4), (997.5, 999.5, 4), (1003.7, 1005.4, 4)] # Harmonics + + h_notched = fade(notch_data(h, sampling_rate, notch_locations_and_sizes)) + htilde_notched = dt * np.fft.rfft(h_notched) + + # Finally we can plot and listen to the notched data + _fig, (_ax1, _ax2), _audio = plot_td_and_fd_mpl(t, h_notched, frequencies, htilde_notched, htilde=dt*np.fft.rfft(fade(h))); + plt.show() + _audio + return h_notched, htilde_notched + + +@app.cell(hide_code=True) +def _(mo): + mo.md(r"""Those spikes have gone away pretty nicely in the frequency domain, but this is almost the same as the raw data. So we try again to auto-equalize:""") + return + + +@app.cell +def _( + InterpolatedUnivariateSpline, + fade, + frequencies, + h_notched, + htilde1, + htilde_notched, + noise_spectral_density_interpolator, + np, + plot_td_and_fd_mpl, + plt, + sampling_rate, + scipy, + t, +): + # Now we'll estimate the noise spectrum again + _number_of_chunks = 8 + _points_per_chunk = 2**int(np.log2(len(h_notched)/_number_of_chunks)) + f_noise1, noise_welch1 = scipy.signal.welch(h_notched, sampling_rate, nperseg=_points_per_chunk) + noise_spectral_density1 = np.sqrt(2 * len(h_notched) * noise_welch1 / sampling_rate) + noise_spectral_density_interpolator1 = InterpolatedUnivariateSpline(f_noise1,noise_spectral_density1) + + # And we'll filter the data using this new estimate + htilde_notched_equalized = htilde_notched / noise_spectral_density_interpolator(frequencies) + h_notched_equalized = fade(sampling_rate * np.fft.irfft(htilde_notched_equalized)) + + _fig, (_ax1, _ax2), _audio = plot_td_and_fd_mpl(t, h_notched_equalized, frequencies, htilde_notched_equalized, htilde=1e21*htilde1); + plt.show() + _audio + return (h_notched_equalized,) + + +@app.cell(hide_code=True) +def _(mo): + mo.md(r"""We're starting to see the signal a little more clearly, and there are no big spikes in the frequency domain, suggesting that we've done a pretty good job of filtering. The final step is to simply cut off the low frequencies where the noise swamped the signal, and the high frequencies where we don't expect any signal at all.""") + return + + +@app.cell +def _( + bandpass, + dt, + frequencies, + h_notched_equalized, + htilde1, + np, + plot_td_and_fd_mpl, + plt, + sampling_rate, + t, +): + h_filtered = bandpass(h_notched_equalized, sampling_rate, lower_end=35.0, upper_end=265.0) + h_filtered_tilde = dt * np.fft.rfft(h_filtered) + + _fig, (_ax1, _ax2), _audio = plot_td_and_fd_mpl(t, h_filtered, frequencies, h_filtered_tilde, htilde=1e22*htilde1); + plt.show() + _audio + return h_filtered, h_filtered_tilde + + +@app.cell(hide_code=True) +def _(mo): + mo.md( + r""" + Finally, we've gotten a pretty clear signal. It stands out more than anything you could *credibly* achieve by hand with the graphic equalizer. It follows the noise curve reasonably well in the most sensitive band, except for those spikes that we know are just noise. And it falls off very quickly outside of the sensitive band. + + Most importantly, we've cleaned up this signal without any tweaking that might apply only to this system. In fact, we can make a function that encapsulates everything we've done and returns the filtered signal, and then apply that function to a different signal and still get a nice result. + """ + ) + return + + +@app.function +def filter_signal(raw_signal, sampling_rate, upper_bandpass_frequency=265.0, noisy_signal=None): + import numpy as np + from scipy.interpolate import InterpolatedUnivariateSpline + from scipy.signal import welch + from utilities import fade, notch_data, bandpass + + # First, we fade in at the beginning and out at the end + filtered_signal = fade(raw_signal) + frequencies = np.fft.rfftfreq(len(filtered_signal), d=1/sampling_rate) + + # We defined these before, outside this function; do it again to make sure they didn't change + notch_locations_and_sizes = [ + (35.1, 37.1, 0.25), (35.7, 36., 0.8), (36.6, 36.8, 1.3), (40.9, 41.0, 2), + (59.9, 60.1, 4), (119.9, 120.1, 3), (179.9, 180.1, 4), + (299.47, 299.7, 2), (303.2, 303.35, 2), (310., 327., 0.25), (331.7, 332.2, 2), + (500.5, 503.1, 1.0), (504.7, 504.9, 1.5), (507.0, 508.7, 1.5), + (991.2, 992.8, 4), (993.7, 997.0, 4), (997.5, 999.5, 4), (1003.7, 1005.4, 4)] + + # Now we notch the data and make sure it's still faded + filtered_signal = fade(notch_data(filtered_signal, sampling_rate, notch_locations_and_sizes)) + + # Do the same to the noisy signal + if noisy_signal is None: + noisy_signal = filtered_signal + else: + noisy_signal = fade(noisy_signal) + noisy_signal = fade(notch_data(noisy_signal, sampling_rate, notch_locations_and_sizes)) + + # Estimate the noise spectrum + number_of_chunks = 8 + points_per_chunk = 2**int(np.log2(len(noisy_signal)/number_of_chunks)) + f_noise, noise_welch = welch(noisy_signal, sampling_rate, nperseg=points_per_chunk) + noise_spectral_density = np.sqrt(2 * len(noisy_signal) * noise_welch / sampling_rate) + noise_interpolator = InterpolatedUnivariateSpline(f_noise, noise_spectral_density) + + # Equalize the data using this noise estimate + filtered_signal_tilde = np.fft.rfft(filtered_signal) / sampling_rate + filtered_signal_tilde = filtered_signal_tilde / noise_interpolator(frequencies) + filtered_signal = fade(sampling_rate * np.fft.irfft(filtered_signal_tilde)) + + # Finally, bandpass the equalized notched data + filtered_signal = bandpass(filtered_signal, sampling_rate, lower_end=35.0, + upper_end=upper_bandpass_frequency) + + return filtered_signal + + +@app.cell(hide_code=True) +def _(mo): + mo.md(r"""The cell above defines the function. Now we'll load the data from LIGO Livingston, and filter it.""") + return + + +@app.cell +def _( + dt, + frequencies, + h5py, + io, + np, + plot_td_and_fd_mpl, + plt, + requests, + sampling_rate, + t, +): + Livingston_file_path = "https://raw.githubusercontent.com/chengj7/MatchedFiltering/refs/heads/binder/content/data/L-L1_LOSC_4_V1-1126259446-32.hdf5" + Livingston_response = requests.get(Livingston_file_path) + + Livingston_file_bytes = io.BytesIO(Livingston_response.content) + + # Load the raw data from LIGO Hanford + with h5py.File(Livingston_file_bytes, 'r') as f2: + l = f2['strain/Strain'][:] # Time of event is 16.4 + + # Now Fourier transform the raw data + ltilde = dt * np.fft.rfft(l) + + # Filter it using our function + l_filtered = filter_signal(l, sampling_rate) + + # Now Fourier transform the filtered data + l_filtered_tilde = dt * np.fft.rfft(l_filtered) + + # Finally plot and play it + _fig, (_ax1, _ax2), _audio = plot_td_and_fd_mpl(t, l_filtered, frequencies, l_filtered_tilde, h=l, htilde=1e22*ltilde); + plt.show() + _audio + return l, l_filtered, l_filtered_tilde + + +@app.cell(hide_code=True) +def _(mo): + mo.md( + r""" + The Livingston data is a little quieter because of how the detectors were pointed, so the peak isn't as far above the noise as it was with Hanford data, but it's still pretty clear. The noise curve looks a little different, but our filtering is still similar enough that it works nicely. + + We can plot the two of them together to see how close they are. We need to flip the sign of one of the signals because the two detectors are rotated with respect to each other, and we have to shift Livingston's data $7.2\, \mathrm{ms}$ forward in time because that's how long it took the gravitational waves to travel from one detector to the other. + """ + ) + return + + +@app.cell +def _(h_filtered, l_filtered, mo, np, plt, sampling_rate, t): + plt.close() + plt.plot(t+0.0072, -l_filtered, label='Livingston') + plt.plot(t, h_filtered, label='Hanford') + plt.xlim(16.2, 16.5) + plt.xlabel('Time (seconds)') + plt.ylabel('Detector strain $h$ (dimensionless)') + plt.title('Filtered detector data from the GW150914 event') + plt.grid() + plt.legend(); + + # Here, we'll play the sounds with Livingston in the left ear and Hanford in the right + _audio = mo.audio( + src=np.vstack((np.roll(-l_filtered, int(0.0072*sampling_rate)), h_filtered)), + rate=int(sampling_rate), + ) + + plt.show() + _audio + return + + +@app.cell(hide_code=True) +def _(mo): + mo.md( + r""" + These are two pretty large signals. They also match each other really nicely, and they arrived at different places on the earth close in time to each other. Taken together, this already argues pretty strongly that these are gravitational waves. In fact, the LIGO collaboration's analysis of their data suggest that — without any black holes — a coincidence like this would only happen no more than once in every 8400 years of data. Considering that their analysis only covered 16 days of data, it's pretty unlikely to just be coincidence. But that's a very crude way of looking at the data. + + We can do much better if we try to fit this data with an analytical waveform. In fact, we can use an expected signal to find gravitational waves in our data even when they're completely swamped by the noise and we have no chance of seeing or hearing them. More than just *detecting* the waves, we'll also be able to *measure* the systems that generated them if we try lots of different "expected" signals and see which one matches best. + """ + ) + return + + +@app.cell(hide_code=True) +def _(mo): + mo.md( + r""" +
+ # 6. Digging signal out of noise with a model waveform + """ + ) + return + + +@app.cell(hide_code=True) +def _(mo): + mo.md( + r""" + We've really improved the signal just by filtering out what we suspect to be noise. But most signals LIGO will see will be much smaller than this one. And we need some more quantitative assessment than "Yeah, that sounds right." We need to compare the data to a model. + + If we have a model waveform from some numerical simulation, we can use that information to test if the model signal is present in the data. The trick is to line the model up with where we think it is in the data, and then just multiply the model times the data at each point. Places where the model is positive and the data is positive will stay positive; places where they are both negative will multiply to a positive. So anywhere the model and the data are the same, we can expect to find a positive product. Places where they are different will give us a negative product. + + If the product is more positive than negative for a lot of the time, we can say that our signal is probably present in the data. If the signal isn't the same as the data, their product will just randomly wander back and forth between positive and negative. So to make this more quantitative still, we can look at the average value of the product. To make this all very simple, if our detector data is $d(t)$ and our simulated data is $s(t)$, we'll evaluate the correlation + \begin{equation} + c = \int_T\ d(t)\, s(t)\, dt. + \end{equation} + If this is a large positive number, we have good evidence that $s$ is present in $d$. + + First, though, we have to make sure that our model is lined up with the data and looks like it's found in the data. We'll just plot the simulated signal right on top of the filtered detector data. + """ + ) + return + + +@app.cell +def _(h_filtered, l_filtered, mo, np, nr, plt, sampling_rate, t): + plt.close() + plt.plot(t+0.0072, -l_filtered, label='Livingston') + plt.plot(t, h_filtered, label='Hanford') + plt.plot(t-0.002, 8e21*nr, label='Simulated') + plt.xlim(16.0, 16.5) + plt.xlabel('Time (seconds)') + plt.ylabel('Detector strain $h$ (dimensionless)') + plt.title('Filtered detector data and simulated signal') + plt.grid() + plt.legend(loc='upper left'); + + # Here, we'll play the sounds with Livingston in the left ear, Hanford in the right, + # and NR in the center. We "roll" the Livingston and simulated data as a simple way + # of shifting them in time. + _audio = mo.audio( + src=np.vstack(( + np.roll(-l_filtered, int(0.0072*sampling_rate)), + h_filtered, + np.roll(8e21*nr, int(-0.002*sampling_rate)), + )), + rate=int(sampling_rate), + ) + + plt.show() + _audio + return + + +@app.cell(hide_code=True) +def _(mo): + mo.md(r"""This looks fishy because early on, the simulated signal is quite large, but the detector data is clearly much smaller. We might conclude that the data does not actually contain this signal. However, we've done nothing to the simulated waveform, whereas we've applied very strong filtering to the detector data. In particular, the noise gets large at low frequencies, so we've reduced the amplitude of the data there. But early on, our simulated signal has lots of power at low frequencies. So if we want to see how the simulated data compare to the measured data, we should treat it the same: we need to filter the simulated waveform.""") + return + + +@app.cell +def _(dt, h, h_filtered, l, l_filtered, mo, np, nr, plt, sampling_rate, t): + # Filter and rescale arbitrarily to match amplitude of data + nr_filtered_h = 0.55 * filter_signal(nr, sampling_rate, noisy_signal=h) + nr_filtered_h_tilde = dt * np.fft.rfft(nr_filtered_h) + nr_filtered_l = 0.55 * filter_signal(nr, sampling_rate, noisy_signal=l) + nr_filtered_l_tilde = dt * np.fft.rfft(nr_filtered_l) + + # Now, plot and play the *filtered* NR data on top of the filtered detector data + plt.close() + plt.plot(t+0.0072, -l_filtered, label='Livingston') + plt.plot(t, h_filtered, label='Hanford') + plt.plot(t-0.002, nr_filtered_h, label='Simulated and filtered') + plt.xlim(16.0, 16.5) + plt.xlabel('Time (seconds)') + plt.ylabel('Detector strain $h$ (dimensionless)') + plt.title('Filtered detector data and filtered simulated signal') + plt.grid() + plt.legend(loc='upper left'); + + _audio = mo.audio( + src=np.vstack(( + np.roll(-l_filtered, int(0.0072*sampling_rate)), + h_filtered, + np.roll(nr_filtered_h, int(-0.002*sampling_rate)), + )), + rate=int(sampling_rate), + ) + + plt.show() + _audio + return ( + nr_filtered_h, + nr_filtered_h_tilde, + nr_filtered_l, + nr_filtered_l_tilde, + ) + + +@app.cell(hide_code=True) +def _(mo): + mo.md( + r""" + Now this looks believable. We still have a lot of noise in the detector data, but we can believe that our signal is basically added to that background noise. + + So we can now try our trick of multiplying the detector data by the simulation data. + """ + ) + return + + +@app.cell +def _( + h_filtered, + l_filtered, + mo, + np, + nr_filtered_h, + nr_filtered_l, + plt, + scipy, + t, +): + # Add small time offsets to the filtered detector data, to align the measured data to the model, + # and evaluate the correlation. (The precise time offsets will be derived below.) + l_correlation = np.roll(-l_filtered, 37) * nr_filtered_h + h_correlation = np.roll(+h_filtered, 7) * nr_filtered_l + + # Integrate the correlation functions over time + c_l = scipy.integrate.simpson(y=l_correlation, x=t) + c_h = scipy.integrate.simpson(y=h_correlation, x=t) + + # Plot the correlation functions as functions of time + plt.close() + plt.plot(t, l_correlation, label='Livingston') + plt.plot(t, h_correlation, label='Hanford') + plt.grid() + plt.xlim(16.25, 16.5) + plt.xlabel('Time (seconds)') + plt.ylabel('Correlation between data and simulated signal') + plt.legend(); + + mo.vstack([ + mo.md(rf"$c_{{\mathrm{{Livingston}}}} = {c_l:.4f}$"), + mo.md(rf"$c_{{\mathrm{{Hanford}}}} = {c_h:.4f}$"), + plt.gcf() + ]) + return + + +@app.cell(hide_code=True) +def _(mo): + mo.md(r"""We find that we really do see lots of positive numbers right around the merger, and relatively few negative numbers. This is very unlikely to happen just by chance.""") + return + + +@app.cell(hide_code=True) +def _(mo): + mo.md( + r""" + ## Questions + + * What happens if you shift the simulated signal by a few seconds, so that it's not a good model for the detector data? + * What does the correlation look like as a function of time if you have the wrong shift, and how does it compare to the correlation when you have the right time offset? + * What about the integral of the correlation? + * Do these numbers seem a little arbitrary to you? What happens if the source is twice as close, so the amplitude is twice as large? Can you normalize our correlation quantity so that it never gets bigger than $1$? (That way, you can compare the correlations using different simulated waveforms without worrying about their scale.) + +
+ """ + ) + return + + +@app.cell(hide_code=True) +def _(mo): + mo.md(r"""# 7. Speeding up the process for LIGO searches""") + return + + +@app.cell(hide_code=True) +def _(mo): + mo.md( + r""" + LIGO searches for signals by evaluating the correlation for huge numbers of possible systems, using huge numbers of "simulated" waveforms. This is a very computationally expensive problem. But one thing that makes it even worse is that we don't know when a binary might be merging out in the universe, so we have to shift the simulated waveform around in time to find the best correlation. On top of that, we don't know what orientation the binary might have, so we have to rotate the simulated waveform to find the best correlation. If we had to rotate the simulated waveform for every possible rotation, offset the simulated waveform for every possible time offset, and then multiply the waveforms and integrate for each possibility, LIGO would never be able to work quickly enough to actually find a system. But we can do better with some clever math tricks. + + To start with, assume that we have the right rotation and time offset. We can find a different way of integrating the correlation in time. The [convolution theorem](https://en.wikipedia.org/wiki/Convolution_theorem) tells us that the product $g(t)\, h(t)$ is equal to the inverse Fourier transform of the convolution of the Fourier transforms: + $$ + \begin{aligned} + g(t)\, h(t) + &= \int_{-\infty}^{\infty}\ \left[\int_{-\infty}^{\infty}\ \tilde{g}(f')\, \tilde{h}(f-f')\, df'\right]\, e^{2\pi i f t}\, df, \\ + &= \int_{-\infty}^{\infty}\ \left[\int_{-\infty}^{\infty}\ \tilde{g}(f')\, \tilde{h}^\ast(f'-f)\, df'\right]\, e^{2\pi i f t}\, df. + \end{aligned} + $$ + In the second line, we use the fact that our signals are real, so $\tilde{h}(f-f') = \tilde{h}^\ast(f'-f)$. Now, if we integrate both sides over $t$, we can exchange the order of integrations and use a formula for the [Dirac $\delta$ function](https://en.wikipedia.org/wiki/Dirac_delta_function) to eliminate the integrals over $t$ and $f$, so we're left with + $$ + \begin{equation} + \tag{1} + \int_{-\infty}^{\infty}\ g(t)\, h(t)\, dt = \int_{-\infty}^{\infty}\ \tilde{g}(f')\, \tilde{h}^\ast(f')\, df'. + \end{equation} + $$ + That is, we can evaluate our correlation in the time domain or the frequency domain, as we see fit. + + But now, let's think about the time offset — and ignore the unknown rotation for a moment. Since we don't really know when any binary might be merging in the universe, we have to find the best correlation as we shift the simulated data by some $\delta t$. It's not too hard to prove this fact about the Fourier transform: If $g(t) \mapsto \tilde{g}(f)$, then + $$ + \begin{equation} + g(t + \delta t) \mapsto \tilde{g}(f)\, e^{2\pi\, i\, f\, \delta t}. + \end{equation} + $$ + So we can generalize the equation above to read + $$ + \begin{equation} + \tag{2} + \int_{-\infty}^{\infty}\ g(t + \delta t)\, h(t)\, dt = \int_{-\infty}^{\infty}\ \tilde{g}(f')\, \tilde{h}^\ast(f')\, e^{2\pi\, i\, f\, \delta t}\, df'. + \end{equation} + $$ + The right-hand side is just the inverse Fourier transform of $\tilde{g}(f')\, \tilde{h}^\ast(f')$, but this is easy and fast to compute! In this case, the inverse Fourier transform is a function of $\delta t$, so we can compute it, and then just pick the largest value, and we've automatically optimized the time offset. + + Now let's consider the rotation. If you dig down into the theory of gravitational waves, you'll find that they're actually best described as complex numbers — or more specifically, a gravitational wave is a complex-valued transverse wave. Our detectors just pick out one part of this complex field because it would cost about twice as much to pick out both parts. If you were to rotate the detector, you would also rotate the phase of the underlying complex field, but the detector would still just pick out one part — say, the real part. That is, the quantity $g$ above is actually the real part of some complex $G$, for which $G \mapsto e^{i\phi} G$. So, we have + $$ + \begin{equation} + g = \Re\{G\} \mapsto \Re\{e^{i\phi} G\} = g\cos\phi - g'\sin\phi, + \end{equation} + $$ + where $g'=\Im\{G\}$. + + So far in this section, we've been assuming that both signals $g$ and $h$ are already "equalized" by the noise spectrum. The squared noise spectrum is usually written $S_n(f)$. Using this, we define the "match" between two not-yet-equalized signals to be + $$ + \begin{aligned} + M(g, h) + &= \max_{\delta t}{}\ \int_{-\infty}^{\infty}\ g(t + \delta t)\, h(t)\, dt, \\ + &= \max_{\delta t}{}\ \int_{-\infty}^{\infty}\ \frac{\tilde{g}(f)\, \tilde{h}^\ast(f)} {S_n(f)}\, e^{2\pi\, i\, f\, \delta t}\, df. + \end{aligned} + $$ + The last form is just the inverse Fourier transform, and since the (inverse) FFT is such an efficient algorithm, it can be computed very quickly, and we just pick out the largest element of the result to get our answer. This is the actual formula that LIGO uses to run its searches. + """ + ) + return + + +@app.cell(hide_code=True) +def _(mo): + mo.md(r"""Now, to see how this works, we can apply it to the GW150914 data from above. We just take the Fourier-domain filtered detector data, multiply it by the Fourier-domain filtered simulated template signal (conjugated), and take the inverse FFT. The maximum value will tell us how much to offset the detector data to match the simulated signal as well as possible.""") + return + + +@app.cell +def _( + h_filtered_tilde, + l_filtered_tilde, + np, + nr_filtered_h_tilde, + nr_filtered_l_tilde, +): + match_h = np.fft.irfft(h_filtered_tilde * nr_filtered_h_tilde.conjugate()) + match_l = np.fft.irfft(l_filtered_tilde * nr_filtered_l_tilde.conjugate()) + + optimal_offset_l = match_l.size-np.argmax(abs(match_l)) + optimal_offset_h = match_h.size-np.argmax(abs(match_h)) + + print("Index of the optimal Livingston offset:", optimal_offset_l) + print("Index of the optimal Hanford offset:", optimal_offset_h) + return + + +@app.cell(hide_code=True) +def _(mo): + mo.md(r"""These are the origins of the mysterious 37 and 7 we used at the end of the previous section to get the best correlation between the data and the template signal.""") + return + + +@app.cell(hide_code=True) +def _(mo): + mo.md( + r""" + ## Questions + + * Can you derive the equation for the Fourier transform of a time-offset signal? + * Can you derive the equation for the correlation in the frequency domain? + * How can we normalize the input waveforms? + """ + ) + return + + +@app.cell(hide_code=True) +def _(mo): + mo.md( + r""" + # 8. More detections! + + Since the first detection, there have been several other detections and "triggers". A "trigger" is what LIGO calls an event that initially looks like a detection, but has not been evaluated in enough detail for them to be confident that it actually is an astrophysical phenomenon. + + You have been given some data of your own, containing data very similar to one of the four events that LIGO has identified so far. Your job is to find out which one. To make things a little easier on you, we first condense all of the fancy filtering and matching done above into a single function: + """ + ) + return + + +@app.cell +def _(Latex, display, dt, fade, h5py, np, plt, sampling_rate, scipy, t): + def show_matches(h, l, nr, phase_offset=0.0): + + if isinstance(h, str): + with h5py.File(h) as f: + h = f['strain/Strain'][:] + htilde = dt * np.fft.rfft(h) + h_filtered = filter_signal(h, sampling_rate, upper_bandpass_frequency=512.0) + h_filtered_tilde = dt * np.fft.rfft(h_filtered) + + if isinstance(l, str): + with h5py.File(l) as f: + l = f['strain/Strain'][:] + ltilde = dt * np.fft.rfft(l) + l_filtered = filter_signal(l, sampling_rate, upper_bandpass_frequency=512.0) + l_filtered_tilde = dt * np.fft.rfft(l_filtered) + + if isinstance(nr, str): + with h5py.File(nr) as f: + nr = fade((np.exp(phase_offset) * (f['template'][0][:] + 1j*f['template'][1][:])).real) + nrtilde = dt * np.fft.rfft(nr) + nr_filtered_h = filter_signal(nr, sampling_rate, upper_bandpass_frequency=512.0, noisy_signal=h) + nr_filtered_h_tilde = dt * np.fft.rfft(nr_filtered_h) + nr_filtered_l = filter_signal(nr, sampling_rate, upper_bandpass_frequency=512.0, noisy_signal=l) + nr_filtered_l_tilde = dt * np.fft.rfft(nr_filtered_l) + + match_h = np.fft.irfft(h_filtered_tilde * nr_filtered_h_tilde.conjugate()) + match_l = np.fft.irfft(l_filtered_tilde * nr_filtered_l_tilde.conjugate()) + + optimal_offset_l = np.argmax(abs(match_l)) + optimal_offset_h = np.argmax(abs(match_h)) + + print("Index of the optimal Livingston offset:", optimal_offset_l) + print("Index of the optimal Hanford offset: ", optimal_offset_h) + + # Add small time offsets to the filtered detector data, to align the measured data to the model. + # (These precise offsets will be derived below.) + l_correlation = np.roll(l_filtered, -optimal_offset_l) * nr_filtered_l + h_correlation = np.roll(h_filtered, -optimal_offset_h) * nr_filtered_h + + # Integrate the correlation functions over time + c_l = scipy.integrate.simps(l_correlation, t) + c_h = scipy.integrate.simps(h_correlation, t) + display(Latex(r'$c_{{\mathrm{{Livingston}}}} = {0:.4f}$'.format(c_l))) + display(Latex(r'$c_{{\mathrm{{Hanford}}}} = {0:.4f}$'.format(c_h))) + + # Plot the correlation functions as functions of time + plt.close() + plt.figure() + plt.plot(t, np.sign(c_l)*l_correlation, label='Livingston') + plt.plot(t, np.sign(c_h)*h_correlation, label='Hanford') + plt.grid() + plt.xlim(15.75, 16.1) + plt.xlabel('Time (seconds)') + plt.ylabel('Correlation between data and simulated signal') + plt.legend() + plt.show(); + + + # You can use that function for any of the three events (or one trigger) with function calls like these: + #show_matches('data/H-H1_LOSC_4_V1-1126259446-32.hdf5', 'data/L-L1_LOSC_4_V1-1126259446-32.hdf5', 'data/GW150914_4_template.hdf5', 0.75j*np.pi) + #show_matches('data/H-H1_LOSC_4_V1-1128678884-32.hdf5', 'data/L-L1_LOSC_4_V1-1128678884-32.hdf5', 'data/LVT151012_4_template.hdf5', 0.024j*np.pi) + #show_matches('data/H-H1_LOSC_4_V1-1135136334-32.hdf5', 'data/L-L1_LOSC_4_V1-1135136334-32.hdf5', 'data/GW151226_4_template.hdf5', 0.0) + #show_matches('data/H-H1_LOSC_4_V1-1167559920-32.hdf5', 'data/L-L1_LOSC_4_V1-1167559920-32.hdf5', 'data/GW170104_4_template.hdf5', 0.08j*np.pi) + return + + +@app.cell(hide_code=True) +def _(mo): + mo.md(r"""Now, retrieve your data:""") + return + + +@app.cell +def _(): + return + + +@app.cell(hide_code=True) +def _(mo): + mo.md(r"""Figure out which of the four events best matches your data, and how it's not quite the same as the original LIGO event.""") + return + + +@app.cell +def _(): + #your code goes here ... + return + + +@app.cell +def _(): + return + + +@app.cell +def _(): + return + + +@app.cell +def _(): + return + + +if __name__ == "__main__": + app.run() From 248e1d929ff27ebd0d9af81b34b48cdcd8e1213f Mon Sep 17 00:00:00 2001 From: chengj7 <137737242+chengj7@users.noreply.github.com> Date: Tue, 22 Sep 2026 17:36:50 -0400 Subject: [PATCH 29/35] Add script metadata for Python version and dependencies Added metadata for script requirements and dependencies. --- content/_matchedfiltering_mpl.py | 15 +++++++++++++++ 1 file changed, 15 insertions(+) diff --git a/content/_matchedfiltering_mpl.py b/content/_matchedfiltering_mpl.py index efaed1e..1554614 100644 --- a/content/_matchedfiltering_mpl.py +++ b/content/_matchedfiltering_mpl.py @@ -1,3 +1,18 @@ +# /// script +# requires-python = ">=3.13" +# dependencies = [ +# "ipython==9.7.0", +# "marimo==0.17.8", +# "matplotlib==3.10.7", +# "numpy==2.3.4", +# "pandas==2.3.3", +# "plotly==6.4.0", +# "h5py==3.16.0", +# "requests==2.32.5", +# "scipy==1.16.3", +# ] +# /// + import marimo __generated_with = "0.16.5" From efa3746327bd41ac3b89b2ca4c97e469f163a709 Mon Sep 17 00:00:00 2001 From: chengj7 <137737242+chengj7@users.noreply.github.com> Date: Tue, 22 Sep 2026 17:38:54 -0400 Subject: [PATCH 30/35] Update pyproject.toml From 9c4aba2cf5d9672b3414735c704e7a62ca9ba737 Mon Sep 17 00:00:00 2001 From: chengj7 <137737242+chengj7@users.noreply.github.com> Date: Tue, 22 Sep 2026 17:45:07 -0400 Subject: [PATCH 31/35] Remove unused cell function from _matchedfiltering_mpl.py Removed unused cell function that prints import statement. --- content/_matchedfiltering_mpl.py | 6 ------ 1 file changed, 6 deletions(-) diff --git a/content/_matchedfiltering_mpl.py b/content/_matchedfiltering_mpl.py index 1554614..8b026be 100644 --- a/content/_matchedfiltering_mpl.py +++ b/content/_matchedfiltering_mpl.py @@ -142,12 +142,6 @@ def _(): ) -@app.cell -def _(script_response): - print("import marimo as mo" in script_response.text) - return - - @app.cell(hide_code=True) def _(mo): mo.md( From ef785434acd35a42339d38622cd689a9ac8ad506 Mon Sep 17 00:00:00 2001 From: chengj7 <137737242+chengj7@users.noreply.github.com> Date: Thu, 15 Oct 2026 21:14:43 -0400 Subject: [PATCH 32/35] Delete content/matchedfiltering.py --- content/matchedfiltering.py | 1273 ----------------------------------- 1 file changed, 1273 deletions(-) delete mode 100644 content/matchedfiltering.py diff --git a/content/matchedfiltering.py b/content/matchedfiltering.py deleted file mode 100644 index 29ecd41..0000000 --- a/content/matchedfiltering.py +++ /dev/null @@ -1,1273 +0,0 @@ -# /// script -# requires-python = ">=3.13" -# dependencies = [ -# "ipython==9.7.0", -# "marimo==0.17.8", -# "matplotlib==3.10.7", -# "numpy==2.3.4", -# "pandas==2.3.3", -# "plotly==6.4.0", -# "h5py==3.16.0", -# "requests==2.32.5", -# "scipy==1.16.3", -# ] -# /// - -import marimo - -__generated_with = "0.23.13" -app = marimo.App(width="medium") - - -@app.cell -def _(): - import marimo as mo - - return (mo,) - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - # 1. Introduction - """) - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - ## 1.1 What are we doing? - """) - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - We're doing a little interactive project to give you a better feel for how LIGO data analysis actually works. In particular, we'll be doing **matched filtering** of some data, including the data from the historic first detection of gravitational waves, GW150914. - - You can kind of think of LIGO as a really sensitive microphone, and the data that comes out is like a sound recording. (Except, of course, that sound requires air, while gravitational waves travel through spacetime itself.) In fact, if you go to the LIGO control room, they'll often play the data over speakers, because this is a really useful way of thinking about the data. It even happens to be in the right range for human hearing. So we'll be listening to LIGO data and gravitational waveforms. - - One of the first things you'll discover about the data is that it's full of noise, so we'll need to deal with that noise to pull out our signal. We'll start off with the simplest way to deal with noise, involving the Fourier transform, and find that it actually works well enough to let us hear the GW150914 signal. But if we want to do real science, we'll need to do better, so we'll introduce some real LIGO data analysis, including matched filters. - """) - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - ## 1.2 What are we looking at? - """) - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - This is a [Jupyter notebook](https://jupyter.org/) (formerly known as an [IPython notebook](http://ipython.org/notebook.html)). It's connected to an actual python session, but it runs through a web browser, so we can format things nicely and give some explanations, and so you don't have to copy-and-paste all the instructions into a normal python session. Plus, you can edit the code and explore the data interactively. It's meant to look and work kind of like Mathematica, if you've ever used that before. (And if you don't care for python, Jupyter also handles [Julia](http://nbviewer.ipython.org/url/jdj.mit.edu/~stevenj/IJulia%20Preview.ipynb), [R](https://github.com/IRkernel/IRkernel), [IDL](https://github.com/lstagner/idl_kernel), and numerous other languages.) - - Each of the sections in gray with something like "`In[1]:`" in front of it is called a *cell* and contains code for you to run. Run the code by placing your cursor in the cell, then pressing Shift+Enter. - - As a first example, we'll load some "modules". Basically any time we use python, we'll want to use some modules, which are just containers for a bunch of pre-written code. Run the following cell to load the modules we'll need. - """) - return - - -@app.cell -def _(): - # These are for plotting - #%matplotlib notebook - #%matplotlib inline - #import matplotlib as mpl - #import matplotlib.pyplot as plt - import plotly.graph_objects as go - from plotly.subplots import make_subplots - - - import requests - import os - import sys - import io - #from matplotlib.ticker import FuncFormatter - - # This is an important module whenever you use python for numerics - import numpy as np - - # This lets us read LIGO's data file - import h5py - - # We'll do some fancy signal processing, which is easier with this - import scipy.signal - from scipy.interpolate import InterpolatedUnivariateSpline - - # These are some nice interactive things we'll use in this notebook - #from IPython.display import display, Audio, Latex, clear_output - #import ipywidgets as widgets - - # These are some messy functions I've defined in another file (`utilities.py`) - import time - - script_file_path = f"https://raw.githubusercontent.com/chengj7/MatchedFiltering/refs/heads/binder/content/utilities.py?t={int(time.time())}" - script_response = requests.get(script_file_path) - - base_dir = os.getcwd() - public_dir = os.path.join(base_dir, "public") - os.makedirs(public_dir, exist_ok=True) - - if script_response.status_code == 200: - file_path = os.path.join(public_dir, "utilities.py") - with open(file_path, "w", encoding="utf-8") as f: - f.write(script_response.text) # ← this writes the corrected content to public/utilities.py - else: - raise Exception(f"Failed to download file: {script_response.status_code}") - - sys.path.append(public_dir) - - from utilities import (fade, derivative, plot_td_and_fd_edit, filter_and_plot_edit, add_notch_filter, - filter_cheat, notch_data, bandpass, retrieve_new_data) - - - # This just sets the default size of our plots - #mpl.rcParams['figure.figsize'] = [19.5, 10.0] - return ( - InterpolatedUnivariateSpline, - bandpass, - derivative, - fade, - filter_and_plot_edit, - go, - h5py, - io, - notch_data, - np, - plot_td_and_fd_edit, - requests, - scipy, - script_response, - ) - - -@app.cell -def _(script_response): - print("import marimo as mo" in script_response.text) - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - You won't be expected to understand the python code (though if you do, that's great). But you should run it, follow along with the explanations, and try to understand all the plots and sounds. - - If you put your cursor in a text section and something weird happens, just hit Shift+Enter, and everything will be okay. - """) - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" -
- - # 2. Listening to gravitational waves - """) - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - Here, we'll look at and listen to the "expected signal" from the merger of a black-hole binary like the one measured in GW150914. This signal was created from a simulation of two black holes spiraling in toward each other. - """) - return - - -@app.cell -def _(InterpolatedUnivariateSpline, derivative, fade, io, np, requests): - NR_file_path = "https://raw.githubusercontent.com/chengj7/MatchedFiltering/refs/heads/binder/content/data/NR_GW150914.txt" - NR_response = requests.get(NR_file_path) - #NR_data = np.load(BytesIO(NR_response.content)) - - - # Load the raw NR data produced by the SXS collaboration - nr_complex = np.exp(0.1j*np.pi) * np.loadtxt(io.StringIO(NR_response.text)).view(dtype=complex)[:, 0] - nr = fade(nr_complex.real) - - # # Load LIGO's official template (which isn't as good) - # with h5py.File('data/GW150914_4_template.hdf5') as f: - # nr = np.roll(fade(f['template'][0]), 1807) / 437.666 - - # Set up the time and sampling-frequency information for this signal - sampling_rate = 4096.0 # Hz - dt = 1/sampling_rate - t = np.arange(len(nr)) / sampling_rate - - # Get the time-domain frequency using the complex data - nr_phase = np.unwrap(np.angle(nr_complex)) - nr_angular_frequency = derivative(nr_phase, t) - nr_frequency_interpolator = InterpolatedUnivariateSpline(t, nr_angular_frequency/(2*np.pi)) - - # Now Fourier transform the data, and get the corresponding frequencies - nrtilde = dt * np.fft.rfft(nr) - frequencies = np.fft.rfftfreq(len(nr), dt) - return dt, frequencies, nr, nrtilde, sampling_rate, t - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - We can plot the signal in both the time and frequency domains, and even play the signal over headphones. - - ***CAUTION:*** If you can hear the long, deep inspiral at the beginning of the signal, then the merger may be very loud. Be prepared to take your headphones away from your ears, or to turn down the volume, around the 16 second mark. - """) - return - - -@app.cell -def _(frequencies, nr, nrtilde, plot_td_and_fd_edit, t): - fig1, audio1 = plot_td_and_fd_edit(t, nr, frequencies, nrtilde); - fig1.update_xaxes(range=[t[0], 18.0], row=1,col=1) # Zoom in a little to see mostly signal - - def _nr_frequency_string(time): # Format the frequency as a string in the plot ticks - if time>16.45: - return '' - return '{0:.1f}'.format(abs(_nr_frequency_interpolator([time])[0])) - - fig1.show(config={"staticPlot":True}) - audio1 - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - We notice a few important features in the time domain: - - - The amplitude is shut off entirely at the beginning, but quickly turns on. This is done for technical reasons (to get rid of the so-called Gibbs phenomenon -- but don't worry about it). Of course, a real gravitational-wave signal would extend fairly regularly very far back in time. - - The amplitude is slowly growing at first, but accelerates to a peak, and then basically shuts off again. This part is real. That's the merger and ringdown, where the black holes give off the strongest gravitational waves just as they fall into each other, which happens very suddenly. - - The frequency is slowly increasing at first, but accelerates up to the merger. This is another effect of the inspiral; as energy is given off in gravitational waves, the black holes spiral inwards toward each other and go faster and faster. - - These translate to some interesting features in the frequency domain: - - - The amplitude at low frequencies is shut off. This is for the same reason as the time-domain signal: we just don't have a long enough signal to reach those low frequencies. A real signal would keep going in a straight line off to the upper left. - - Whereas the amplitude of the time-domain waveform *increases* as the frequency increases, the amplitude of the Fourier transform *decreases* as the frequency increases. - - Around $250\, \mathrm{Hz}$, the amplitude drops off very suddenly. This dropoff represents the merger. - - ## Questions - * Can you hear any of the features that you see in the plots? - * Why does the amplitude of the Fourier transform *decrease* as the frequency increases? - * Why does it sound so quiet at the beginning and loud at the highest frequency? - """) - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" -
- - # 3. Listening to detector data - """) - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - The LIGO collaboration claimed that the signal we listened to above (or one very much like it) is found in their detector data from September 14, 2015. [We have that data](https://losc.ligo.org/about/), and we can look for the signal ourselves. First, we'll load the data. The following cell will give us the actual raw data that came out of the detector in Hanford, Washington. - """) - return - - -@app.cell -def _(fade, h5py, io, requests): - Hanford_file_path = "https://raw.githubusercontent.com/chengj7/MatchedFiltering/refs/heads/binder/content/data/H-H1_LOSC_4_V1-1126259446-32.hdf5" - Hanford_response = requests.get(Hanford_file_path) - - Hanford_file_bytes = io.BytesIO(Hanford_response.content) - - # Load the raw data from LIGO Hanford - with h5py.File(Hanford_file_bytes, 'r') as f1: - h = f1['strain/Strain'][:] # Time of event is 16.4 - - # We always want this to turn and off slowly: - h = fade(h) - return (h,) - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - We now have a data set named `h`, which represents the strain measured by the detector. We also want to know the times associated with each data point, and a few useful features of that data set: - """) - return - - -@app.cell -def _(dt, h, np): - # Now Fourier transform the data, and get the corresponding frequencies - htilde1 = dt * np.fft.rfft(h) - frequencies1 = np.fft.rfftfreq(len(h), dt) - return frequencies1, htilde1 - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - Now, we're ready to look at and listen to the raw data containing the GW150914 event. First we'll plot the data as a function of time, then we'll plot (the magnitude of) the Fourier transform as a function of frequency. Finally, we'll also be able to listen to the signal. Remember to be careful of the volume. - """) - return - - -@app.cell -def _(frequencies1, h, htilde1, plot_td_and_fd_edit, t): - fig2, audio2 = plot_td_and_fd_edit(t, h, frequencies1, htilde1) - fig2.show() - audio2 - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - There are controls below the plots that let you zoom in and pan around on the plots. Take a moment to explore the plots and think about these questions: - - - ## Questions - * What happened? Why is this signal nothing at all like the pure gravitational wave we saw above? - * Can you see the signal in the plots? - * Can you hear the signal? - * What are the sources of noise here? - * The raw data sounds generally pretty high-pitched. But looking in the frequency domain, we see that most of the signal is at very low frequencies. Why doesn't the raw data sound low-pitched? - """) - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" -
- - # 4. Digging signal out of noise manually - """) - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - LIGO has a lot of noise. This is entirely expected when dealing with such a sensitive apparatus, but it does swamp the signal. The key to LIGO's success is that the noise is pretty steady (or technically, "stationary"), and the noise is largest at frequencies that aren't the most interesting. We can recover the interesting part of the signal by decreasing the size of the noise. We will do this using a "graphic equalizer". - - A graphic equalizer divides the signal into frequency bands, allows you to adjust the volume in each band, and then combines the signal back into a time-domain signal. You may have seen graphic equalizers in old or high-end stereos: - -
-
- Nowadays, you might see "bass" and "treble" (and maybe even "mid") controls, which do the same thing, but break the signal down into fewer frequency bands.
-
- We're going to do the same thing, but without the old-timey hardware. The cell below sets up a graphic equalizer, then produces the "equalized" data for you to look at and listen to. Mess around with the settings, then press "Recalculate" to see how well you can pick out the signal we're looking for.
- """)
- return
-
-
-@app.cell
-def _(mo, np, sampling_rate):
- #setup
- log2_sampling_rate = int(np.log2(sampling_rate/2))
- frequency_bin_upper_ends = np.logspace(3, log2_sampling_rate, num=2*(log2_sampling_rate-3)+1, base=2)
-
- #equalizer power radio button
- equalizer_power = mo.ui.radio(options=['On','Off'], value='On', label='equalizer')
-
- #equalizer sliders
- equalizer_sliders = mo.ui.array([
- mo.ui.slider(
- start=-200.0, stop=200.0, step=0.5, value=0.0,
- orientation="vertical", show_value=True,
- label=str(int(_freq)),
- )
- for _freq in frequency_bin_upper_ends
- ])
- equal_sliders_hstack = mo.hstack(equalizer_sliders.elements, widths="equal", gap=0)
- equalizer_stack = mo.hstack([equalizer_power, equal_sliders_hstack], align='center')
- return (
- equalizer_power,
- equalizer_sliders,
- equalizer_stack,
- frequency_bin_upper_ends,
- )
-
-
-@app.cell
-def _(mo):
- get_filter_count, set_filter_count = mo.state(0)
-
- #add buttons
- add_notch_filter_button = mo.ui.button(
- label="Add notch filter",
- on_click=lambda _: set_filter_count(lambda n: n + 1),
- )
- notch_filter_power = mo.ui.radio(
- options=["On", "Off"], value="On", label="Notch Filters"
- )
- return add_notch_filter_button, get_filter_count, notch_filter_power
-
-
-@app.cell
-def _(
- add_notch_filter_button,
- equalizer_stack,
- get_filter_count,
- mo,
- notch_filter_power,
-):
- notch_filter_list = mo.ui.array([
- mo.ui.array([
- mo.ui.number(value=0.0, label="Begin"),
- mo.ui.number(value=0.0, label="End"),
- mo.ui.checkbox(label="Use this filter", value=True),
- ])
- for _ in range(get_filter_count())
- ])
-
- notch_filters = mo.hstack(
- [notch_filter_power,
- mo.vstack([
- mo.vstack(
- [mo.hstack(row.elements, justify="space-around")
- for row in notch_filter_list.elements]
- ),
- add_notch_filter_button,
- ],
- align="center",
- ),
- ],
- align="center",
- justify="space-around",
- gap=1,
- )
- mo.vstack([equalizer_stack, notch_filters], align='center')
- return (notch_filter_list,)
-
-
-@app.cell
-def _(
- equalizer_power,
- equalizer_sliders,
- filter_and_plot_edit,
- frequencies,
- frequency_bin_upper_ends,
- h,
- htilde1,
- notch_filter_list,
- notch_filter_power,
- sampling_rate,
- t,
-):
- fig3, audio3 = filter_and_plot_edit(
- h, t, htilde1, sampling_rate, equalizer_sliders, notch_filter_list, equalizer_power, notch_filter_power,
- frequencies, frequency_bin_upper_ends
- )
- fig3.show(config={"staticPlot":True})
- audio3
- return
-
-
-@app.cell(hide_code=True)
-def _(mo):
- mo.md(r"""
- Spend some time playing around with the equalizer to pull out the signal. (Hint: the low and high frequencies are where most of the noise is, and where less of the signal is.)
-
- You can also add some notch filters to eliminate sharp spikes in the frequency-domain data, if you think they're more like noise than signal. A notch filter is like another equalizer slider, except that you get to control where its frequency band begins and ends, and it sets everything in that band as low as it can go.
-
- The signal you're looking for peaks near the middle of the data (around $t=16.4\, \mathrm{sec}$).
-
-
- ## Questions
- * Can you adjust the filters so that you can see the peak amplitude in the time domain? What does it look like when you zoom in? Can you hear it?
- * If you leave the $45\,\mathrm{Hz}$ band in the data, you see (and hear) big slow oscillations in the time-domain amplitude that are *much* slower than $45\,\mathrm{Hz}$. Can you explain where these come from, and why they oscillate like that?
- * How does the largest data point of your filtered data (in the time domain) compare to the largest point in the raw data? Why is this?
- * With good settings, you should be able to see a large spike right in the middle of the data. But there are other spikes, too. How is the middle spike different from the others?
- """)
- return
-
-
-@app.cell(hide_code=True)
-def _(mo):
- mo.md(r"""
- - # 5. Digging signal out of noise automatically - """) - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - There are several ways we could improve the crude filtering we did above with our "equalizer". We'll try two improvements in this section, and more in the following sections. - - First, we could throw in more sliders to adjust for more precise equalization. In fact, the only natural number of sliders is one for every frequency bin in the Fourier transform. But there are already so many sliders for us to adjust that it gets tiring; we'd never be able to manually adjust them all. Plus, we want something automatic that will work in every case. Second, therefore, we can adjust the sliders automatically. Roughly speaking, at frequencies with a lot of noise, we want to filter out a lot of the signal; at frequencies with little noise, we don't want to filter much. - - The first step is to measure the noise as a function of frequency. We already know that the signal is very small during most of our data, so we could define the noise at a particular frequency to just be the magnitude of the Fourier transform of the data. But noise is random, and we've only taken a small sample of this random process, so we'd like to average the spectrum. It turns out that a good way to do this is to split the data into chunks, measure the noise in each chunk, and then average the results — or more precisely the root mean square (RMS). There are some additional tricks to deal smooth out the splitting process, and make sure we use all the data without overcounting some, etc. All these tricks are dealt with in what is called "Welch's method". - """) - return - - -@app.cell -def _(InterpolatedUnivariateSpline, h, np, sampling_rate, scipy): - # Set how many chunks we want to split up the data into. We want to balance the need - # for resolving sharp features in the noise (which would suggest using a small number) - # against averaging enough to reduce the variance (which suggests using a large number). - _number_of_chunks = 8 - - # We want our chunks to have sizes that are powers of 2, which speeds up the Fourier - # transforms involved, but we also want about the right number of chunks. This line - # gives us both, because `int` rounds to the nearest integer. - _points_per_chunk = 2**int(np.log2(len(h)/_number_of_chunks)) - - # Now, we can use Welch's method to automatically estimate the noise spectral density. - # The shenanigans we pull with log2 ensures that the chunks are sized to be a power - # of 2, which speeds up the Fourier transforms involved, but also gives us - # approximately the right number of chunks. - f_noise, _noise_welch = scipy.signal.welch(h, sampling_rate, nperseg=_points_per_chunk) - - # Now we just deal with a little normalization weirdness to define the noise spectral density - noise_spectral_density = np.sqrt(2 * len(h) * _noise_welch / sampling_rate) - - # We'll also need to interpolate onto a finer set of frequencies - noise_spectral_density_interpolator = InterpolatedUnivariateSpline(f_noise,noise_spectral_density) - return f_noise, noise_spectral_density, noise_spectral_density_interpolator - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - We can compare our raw data to the estimated noise spectrum: - """) - return - - -@app.cell -def _( - f_noise, - frequencies, - go, - htilde1, - noise_spectral_density, - np, - sampling_rate, -): - fig4 = go.Figure() - fig4.add_trace(go.Scatter(x=frequencies, y=np.abs(htilde1), name='Raw data')) - fig4.add_trace(go.Scatter(x=f_noise, y=noise_spectral_density, name='Noise estimate')) - fig4.update_xaxes( - title_text='Frequency (Hertz)', type="log", - range=[np.log10(1), np.log10(0.6*sampling_rate)], - showgrid=True, - ) - fig4.update_yaxes( - title_text='Noise spectrum and strain Fourier transform (seconds)', - type="log", showgrid=True, - ) - fig4 - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - If you zoom in, you can see that our estimated noise spectrum is substantially smoother than the raw data, as we hoped. It also emphasizes spikes because we used the RMS instead of just the simple mean. - - So now that we've estimated the noise, we can use it to automatically "equalize" the raw data. Remember that where the noise is large we want a lot of filtering, and where the noise is small we want little filtering. So we just divide the raw data by the noise estimate: - """) - return - - -@app.cell -def _( - fade, - frequencies, - h, - htilde1, - noise_spectral_density_interpolator, - np, - plot_td_and_fd_edit, - sampling_rate, - t, -): - # We simply divide htilde by the noise estimate to "equalize" the data in the frequency domain - htilde_equalized = htilde1 / noise_spectral_density_interpolator(frequencies) - - # Now we transform back to the time domain, and smoothly fade on and off to get rid of loud clicks - h_equalized = fade(sampling_rate * np.fft.irfft(htilde_equalized)) - - # Finally we can plot and listen to the data - fig5, audio5 = plot_td_and_fd_edit(t, h_equalized, frequencies, htilde_equalized, h=h, htilde=1e21*htilde1); - fig5.show() - audio5 - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - Unfortunately, this isn't nearly as good as what we could achieve manually using the graphic equalizer above. If you zoom in, you might be able to convince yourself that the signal is there, and you should be able to hear a little blip at the right time. But unless you knew it was there, you'd have a hard time convincing yourself. Looking at the frequency-domain plot, we see why: There's still a lot of noise at the very high and low frequencies that are much smaller, but not gone. Also, the spikes have not entirely gone away. If you look back at our noise estimate around those spikes, you see that the estimate smears them out. So evidently our way of estimating the noise is not good for very sharp features. - - We can solve each of these problems, however. We'll solve the first by removing the high- and low-frequency components even more than the "equalization" did. We'll solve the second by removing those lines with notch filters before "equalizing" the data. - - The first step is to create notch filters for the spikes we see in the input spectrum. This time, we'll do a slightly better job using smooth notches, instead of the sharp square notches we used above. Here we list each notch (beginning and ending frequencies) and something related to the depth of the notch. This may not seem very automatic, but these spikes are fairly constant, so we can just list them once and use the same list forever. In fact, that's what [LIGO does](https://journals.aps.org/prd/abstract/10.1103/PhysRevD.97.082002). - """) - return - - -@app.cell -def _( - dt, - fade, - frequencies, - h, - notch_data, - np, - plot_td_and_fd_edit, - sampling_rate, - t, -): - notch_locations_and_sizes = [ - (35.1, 37.1, 0.25), (35.7, 36., 0.8), (36.6, 36.8, 1.3), (40.9, 41.0, 2), # Gremlins - (59.9, 60.1, 4), (119.9, 120.1, 3), (179.9, 180.1, 4), # Line noise - (299.47, 299.7, 2), (303.2, 303.35, 2), (310., 327., 0.25), (331.7, 332.2, 2), # Violin modes - (500.5, 503.1, 1.0), (504.7, 504.9, 1.5), (507.0, 508.7, 1.5), # Violin modes - (991.2, 992.8, 4), (993.7, 997.0, 4), (997.5, 999.5, 4), (1003.7, 1005.4, 4)] # Harmonics - - h_notched = fade(notch_data(h, sampling_rate, notch_locations_and_sizes)) - htilde_notched = dt * np.fft.rfft(h_notched) - - # Finally we can plot and listen to the notched data - fig6, audio6 = plot_td_and_fd_edit(t, h_notched, frequencies, htilde_notched, htilde=dt*np.fft.rfft(fade(h))); - fig6.show() - audio6 - return h_notched, htilde_notched - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - Those spikes have gone away pretty nicely in the frequency domain, but this is almost the same as the raw data. So we try again to auto-equalize: - """) - return - - -@app.cell -def _( - InterpolatedUnivariateSpline, - fade, - frequencies, - h_notched, - htilde1, - htilde_notched, - noise_spectral_density_interpolator, - np, - plot_td_and_fd_edit, - sampling_rate, - scipy, - t, -): - # Now we'll estimate the noise spectrum again - _number_of_chunks = 8 - _points_per_chunk = 2**int(np.log2(len(h_notched)/_number_of_chunks)) - f_noise1, noise_welch1 = scipy.signal.welch(h_notched, sampling_rate, nperseg=_points_per_chunk) - noise_spectral_density1 = np.sqrt(2 * len(h_notched) * noise_welch1 / sampling_rate) - noise_spectral_density_interpolator1 = InterpolatedUnivariateSpline(f_noise1,noise_spectral_density1) - - # And we'll filter the data using this new estimate - htilde_notched_equalized = htilde_notched / noise_spectral_density_interpolator(frequencies) - h_notched_equalized = fade(sampling_rate * np.fft.irfft(htilde_notched_equalized)) - - fig7, audio7 = plot_td_and_fd_edit(t, h_notched_equalized, frequencies, htilde_notched_equalized, htilde=1e21*htilde1) - fig7.show() - audio7 - return (h_notched_equalized,) - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - We're starting to see the signal a little more clearly, and there are no big spikes in the frequency domain, suggesting that we've done a pretty good job of filtering. The final step is to simply cut off the low frequencies where the noise swamped the signal, and the high frequencies where we don't expect any signal at all. - """) - return - - -@app.cell -def _( - bandpass, - dt, - frequencies, - h_notched_equalized, - htilde1, - np, - plot_td_and_fd_edit, - sampling_rate, - t, -): - h_filtered = bandpass(h_notched_equalized, sampling_rate, lower_end=35.0, upper_end=265.0) - h_filtered_tilde = dt * np.fft.rfft(h_filtered) - - fig8, audio8 = plot_td_and_fd_edit(t, h_filtered, frequencies, h_filtered_tilde, htilde=1e22*htilde1); - fig8.show() - audio8 - return h_filtered, h_filtered_tilde - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - Finally, we've gotten a pretty clear signal. It stands out more than anything you could *credibly* achieve by hand with the graphic equalizer. It follows the noise curve reasonably well in the most sensitive band, except for those spikes that we know are just noise. And it falls off very quickly outside of the sensitive band. - - Most importantly, we've cleaned up this signal without any tweaking that might apply only to this system. In fact, we can make a function that encapsulates everything we've done and returns the filtered signal, and then apply that function to a different signal and still get a nice result. - """) - return - - -@app.function -def filter_signal(raw_signal, sampling_rate, upper_bandpass_frequency=265.0, noisy_signal=None): - import numpy as np - from scipy.interpolate import InterpolatedUnivariateSpline - from scipy.signal import welch - from utilities import fade, notch_data, bandpass - - # First, we fade in at the beginning and out at the end - filtered_signal = fade(raw_signal) - frequencies = np.fft.rfftfreq(len(filtered_signal), d=1/sampling_rate) - - # We defined these before, outside this function; do it again to make sure they didn't change - notch_locations_and_sizes = [ - (35.1, 37.1, 0.25), (35.7, 36., 0.8), (36.6, 36.8, 1.3), (40.9, 41.0, 2), - (59.9, 60.1, 4), (119.9, 120.1, 3), (179.9, 180.1, 4), - (299.47, 299.7, 2), (303.2, 303.35, 2), (310., 327., 0.25), (331.7, 332.2, 2), - (500.5, 503.1, 1.0), (504.7, 504.9, 1.5), (507.0, 508.7, 1.5), - (991.2, 992.8, 4), (993.7, 997.0, 4), (997.5, 999.5, 4), (1003.7, 1005.4, 4)] - - # Now we notch the data and make sure it's still faded - filtered_signal = fade(notch_data(filtered_signal, sampling_rate, notch_locations_and_sizes)) - - # Do the same to the noisy signal - if noisy_signal is None: - noisy_signal = filtered_signal - else: - noisy_signal = fade(noisy_signal) - noisy_signal = fade(notch_data(noisy_signal, sampling_rate, notch_locations_and_sizes)) - - # Estimate the noise spectrum - number_of_chunks = 8 - points_per_chunk = 2**int(np.log2(len(noisy_signal)/number_of_chunks)) - f_noise, noise_welch = welch(noisy_signal, sampling_rate, nperseg=points_per_chunk) - noise_spectral_density = np.sqrt(2 * len(noisy_signal) * noise_welch / sampling_rate) - noise_interpolator = InterpolatedUnivariateSpline(f_noise, noise_spectral_density) - - # Equalize the data using this noise estimate - filtered_signal_tilde = np.fft.rfft(filtered_signal) / sampling_rate - filtered_signal_tilde = filtered_signal_tilde / noise_interpolator(frequencies) - filtered_signal = fade(sampling_rate * np.fft.irfft(filtered_signal_tilde)) - - # Finally, bandpass the equalized notched data - filtered_signal = bandpass(filtered_signal, sampling_rate, lower_end=35.0, - upper_end=upper_bandpass_frequency) - - return filtered_signal - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - The cell above defines the function. Now we'll load the data from LIGO Livingston, and filter it. - """) - return - - -@app.cell -def _( - dt, - frequencies, - h5py, - io, - np, - plot_td_and_fd_edit, - requests, - sampling_rate, - t, -): - Livingston_file_path = "https://raw.githubusercontent.com/chengj7/MatchedFiltering/refs/heads/binder/content/data/L-L1_LOSC_4_V1-1126259446-32.hdf5" - Livingston_response = requests.get(Livingston_file_path) - - Livingston_file_bytes = io.BytesIO(Livingston_response.content) - - # Load the raw data from LIGO Hanford - with h5py.File(Livingston_file_bytes, 'r') as f2: - l = f2['strain/Strain'][:] # Time of event is 16.4 - - # Now Fourier transform the raw data - ltilde = dt * np.fft.rfft(l) - - # Filter it using our function - l_filtered = filter_signal(l, sampling_rate) - - # Now Fourier transform the filtered data - l_filtered_tilde = dt * np.fft.rfft(l_filtered) - - # Finally plot and play it - fig9, audio9 = plot_td_and_fd_edit(t, l_filtered, frequencies, l_filtered_tilde, h=l, htilde=1e22*ltilde); - fig9.show() - audio9 - return l, l_filtered, l_filtered_tilde - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - The Livingston data is a little quieter because of how the detectors were pointed, so the peak isn't as far above the noise as it was with Hanford data, but it's still pretty clear. The noise curve looks a little different, but our filtering is still similar enough that it works nicely. - - We can plot the two of them together to see how close they are. We need to flip the sign of one of the signals because the two detectors are rotated with respect to each other, and we have to shift Livingston's data $7.2\, \mathrm{ms}$ forward in time because that's how long it took the gravitational waves to travel from one detector to the other. - """) - return - - -@app.cell -def _(go, h_filtered, l_filtered, mo, np, sampling_rate, t): - fig10 = go.Figure() - fig10.add_trace(go.Scatter(x=t+0.0072, y=-l_filtered, name='Livingston')) - fig10.add_trace(go.Scatter(x=t, y=h_filtered, name='Hanford')) - fig10.update_xaxes(title_text='Time (seconds)', range=[16.2, 16.5], showgrid=True) - fig10.update_yaxes(title_text='Detector strain $h$ (dimensionless)', showgrid=True) - fig10.update_layout(title='Filtered detector data from the GW150914 event') - - # Here, we'll play the sounds with Livingston in the left ear and Hanford in the right - audio10 = mo.audio( - src=np.vstack((np.roll(-l_filtered, int(0.0072*sampling_rate)), h_filtered)), - rate=int(sampling_rate), - ) - - fig10.show() - audio10 - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - These are two pretty large signals. They also match each other really nicely, and they arrived at different places on the earth close in time to each other. Taken together, this already argues pretty strongly that these are gravitational waves. In fact, the LIGO collaboration's analysis of their data suggest that — without any black holes — a coincidence like this would only happen no more than once in every 8400 years of data. Considering that their analysis only covered 16 days of data, it's pretty unlikely to just be coincidence. But that's a very crude way of looking at the data. - - We can do much better if we try to fit this data with an analytical waveform. In fact, we can use an expected signal to find gravitational waves in our data even when they're completely swamped by the noise and we have no chance of seeing or hearing them. More than just *detecting* the waves, we'll also be able to *measure* the systems that generated them if we try lots of different "expected" signals and see which one matches best. - """) - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" -
- # 6. Digging signal out of noise with a model waveform - """) - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - We've really improved the signal just by filtering out what we suspect to be noise. But most signals LIGO will see will be much smaller than this one. And we need some more quantitative assessment than "Yeah, that sounds right." We need to compare the data to a model. - - If we have a model waveform from some numerical simulation, we can use that information to test if the model signal is present in the data. The trick is to line the model up with where we think it is in the data, and then just multiply the model times the data at each point. Places where the model is positive and the data is positive will stay positive; places where they are both negative will multiply to a positive. So anywhere the model and the data are the same, we can expect to find a positive product. Places where they are different will give us a negative product. - - If the product is more positive than negative for a lot of the time, we can say that our signal is probably present in the data. If the signal isn't the same as the data, their product will just randomly wander back and forth between positive and negative. So to make this more quantitative still, we can look at the average value of the product. To make this all very simple, if our detector data is $d(t)$ and our simulated data is $s(t)$, we'll evaluate the correlation - \begin{equation} - c = \int_T\ d(t)\, s(t)\, dt. - \end{equation} - If this is a large positive number, we have good evidence that $s$ is present in $d$. - - First, though, we have to make sure that our model is lined up with the data and looks like it's found in the data. We'll just plot the simulated signal right on top of the filtered detector data. - """) - return - - -@app.cell -def _(go, h_filtered, l_filtered, mo, np, nr, sampling_rate, t): - fig11 = go.Figure() - fig11.add_trace(go.Scatter(x=t+0.0072, y=-l_filtered, name='Livingston')) - fig11.add_trace(go.Scatter(x=t, y=h_filtered, name='Hanford')) - fig11.add_trace(go.Scatter(x=t-0.002, y=8e21*nr, name='Simulated')) - fig11.update_xaxes(title_text='Time (seconds)', range=[16.0, 16.5], showgrid=True) - fig11.update_yaxes(title_text='Detector strain $h$ (dimensionless)', showgrid=True) - fig11.update_layout( - title='Filtered detector data and simulated signal', - legend=dict(x=0.01, y=0.99, xanchor='left', yanchor='top'), - ) - - # Here, we'll play the sounds with Livingston in the left ear, Hanford in the right, - # and NR in the center. We "roll" the Livingston and simulated data as a simple way - # of shifting them in time. - audio11 = mo.audio( - src=np.vstack(( - np.roll(-l_filtered, int(0.0072*sampling_rate)), - h_filtered, - np.roll(8e21*nr, int(-0.002*sampling_rate)), - )), - rate=int(sampling_rate), - ) - - fig11.show() - audio11 - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - This looks fishy because early on, the simulated signal is quite large, but the detector data is clearly much smaller. We might conclude that the data does not actually contain this signal. However, we've done nothing to the simulated waveform, whereas we've applied very strong filtering to the detector data. In particular, the noise gets large at low frequencies, so we've reduced the amplitude of the data there. But early on, our simulated signal has lots of power at low frequencies. So if we want to see how the simulated data compare to the measured data, we should treat it the same: we need to filter the simulated waveform. - """) - return - - -@app.cell -def _(dt, go, h, h_filtered, l, l_filtered, mo, np, nr, sampling_rate, t): - # Filter and rescale arbitrarily to match amplitude of data - nr_filtered_h = 0.55 * filter_signal(nr, sampling_rate, noisy_signal=h) - nr_filtered_h_tilde = dt * np.fft.rfft(nr_filtered_h) - nr_filtered_l = 0.55 * filter_signal(nr, sampling_rate, noisy_signal=l) - nr_filtered_l_tilde = dt * np.fft.rfft(nr_filtered_l) - - # Now, plot and play the *filtered* NR data on top of the filtered detector data - fig12 = go.Figure() - fig12.add_trace(go.Scatter(x=t+0.0072, y=-l_filtered, name='Livingston')) - fig12.add_trace(go.Scatter(x=t, y=h_filtered, name='Hanford')) - fig12.add_trace(go.Scatter(x=t-0.002, y=nr_filtered_h, name='Simulated and filtered')) - fig12.update_xaxes(title_text='Time (seconds)', range=[16.0, 16.5], showgrid=True) - fig12.update_yaxes(title_text='Detector strain $h$ (dimensionless)', showgrid=True) - fig12.update_layout( - title='Filtered detector data and filtered simulated signal', - legend=dict(x=0.01, y=0.99, xanchor='left', yanchor='top'), - ) - - audio12 = mo.audio( - src=np.vstack(( - np.roll(-l_filtered, int(0.0072*sampling_rate)), - h_filtered, - np.roll(nr_filtered_h, int(-0.002*sampling_rate)), - )), - rate=int(sampling_rate), - ) - - fig12.show() - audio12 - return ( - nr_filtered_h, - nr_filtered_h_tilde, - nr_filtered_l, - nr_filtered_l_tilde, - ) - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - Now this looks believable. We still have a lot of noise in the detector data, but we can believe that our signal is basically added to that background noise. - - So we can now try our trick of multiplying the detector data by the simulation data. - """) - return - - -@app.cell -def _( - go, - h_filtered, - l_filtered, - mo, - np, - nr_filtered_h, - nr_filtered_l, - scipy, - t, -): - # Add small time offsets to the filtered detector data, to align the measured data to the model, - # and evaluate the correlation. (The precise time offsets will be derived below.) - l_correlation = np.roll(-l_filtered, 37) * nr_filtered_h - h_correlation = np.roll(+h_filtered, 7) * nr_filtered_l - - # Integrate the correlation functions over time - c_l = scipy.integrate.simpson(y=l_correlation, x=t) - c_h = scipy.integrate.simpson(y=h_correlation, x=t) - - # Plot the correlation functions as functions of time - fig13 = go.Figure() - fig13.add_trace(go.Scatter(x=t, y=l_correlation, name='Livingston')) - fig13.add_trace(go.Scatter(x=t, y=h_correlation, name='Hanford')) - fig13.update_xaxes(title_text='Time (seconds)', range=[16.25, 16.5], showgrid=True) - fig13.update_yaxes(title_text='Correlation between data and simulated signal', showgrid=True) - - mo.vstack([ - mo.md(rf"$c_{{\mathrm{{Livingston}}}} = {c_l:.4f}$"), - mo.md(rf"$c_{{\mathrm{{Hanford}}}} = {c_h:.4f}$"), - fig13, - ]) - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - We find that we really do see lots of positive numbers right around the merger, and relatively few negative numbers. This is very unlikely to happen just by chance. - """) - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - ## Questions - - * What happens if you shift the simulated signal by a few seconds, so that it's not a good model for the detector data? - * What does the correlation look like as a function of time if you have the wrong shift, and how does it compare to the correlation when you have the right time offset? - * What about the integral of the correlation? - * Do these numbers seem a little arbitrary to you? What happens if the source is twice as close, so the amplitude is twice as large? Can you normalize our correlation quantity so that it never gets bigger than $1$? (That way, you can compare the correlations using different simulated waveforms without worrying about their scale.) - -
- """) - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - # 7. Speeding up the process for LIGO searches - """) - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - LIGO searches for signals by evaluating the correlation for huge numbers of possible systems, using huge numbers of "simulated" waveforms. This is a very computationally expensive problem. But one thing that makes it even worse is that we don't know when a binary might be merging out in the universe, so we have to shift the simulated waveform around in time to find the best correlation. On top of that, we don't know what orientation the binary might have, so we have to rotate the simulated waveform to find the best correlation. If we had to rotate the simulated waveform for every possible rotation, offset the simulated waveform for every possible time offset, and then multiply the waveforms and integrate for each possibility, LIGO would never be able to work quickly enough to actually find a system. But we can do better with some clever math tricks. - - To start with, assume that we have the right rotation and time offset. We can find a different way of integrating the correlation in time. The [convolution theorem](https://en.wikipedia.org/wiki/Convolution_theorem) tells us that the product $g(t)\, h(t)$ is equal to the inverse Fourier transform of the convolution of the Fourier transforms: - $$ - \begin{aligned} - g(t)\, h(t) - &= \int_{-\infty}^{\infty}\ \left[\int_{-\infty}^{\infty}\ \tilde{g}(f')\, \tilde{h}(f-f')\, df'\right]\, e^{2\pi i f t}\, df, \\ - &= \int_{-\infty}^{\infty}\ \left[\int_{-\infty}^{\infty}\ \tilde{g}(f')\, \tilde{h}^\ast(f'-f)\, df'\right]\, e^{2\pi i f t}\, df. - \end{aligned} - $$ - In the second line, we use the fact that our signals are real, so $\tilde{h}(f-f') = \tilde{h}^\ast(f'-f)$. Now, if we integrate both sides over $t$, we can exchange the order of integrations and use a formula for the [Dirac $\delta$ function](https://en.wikipedia.org/wiki/Dirac_delta_function) to eliminate the integrals over $t$ and $f$, so we're left with - $$ - \begin{equation} - \tag{1} - \int_{-\infty}^{\infty}\ g(t)\, h(t)\, dt = \int_{-\infty}^{\infty}\ \tilde{g}(f')\, \tilde{h}^\ast(f')\, df'. - \end{equation} - $$ - That is, we can evaluate our correlation in the time domain or the frequency domain, as we see fit. - - But now, let's think about the time offset — and ignore the unknown rotation for a moment. Since we don't really know when any binary might be merging in the universe, we have to find the best correlation as we shift the simulated data by some $\delta t$. It's not too hard to prove this fact about the Fourier transform: If $g(t) \mapsto \tilde{g}(f)$, then - $$ - \begin{equation} - g(t + \delta t) \mapsto \tilde{g}(f)\, e^{2\pi\, i\, f\, \delta t}. - \end{equation} - $$ - So we can generalize the equation above to read - $$ - \begin{equation} - \tag{2} - \int_{-\infty}^{\infty}\ g(t + \delta t)\, h(t)\, dt = \int_{-\infty}^{\infty}\ \tilde{g}(f')\, \tilde{h}^\ast(f')\, e^{2\pi\, i\, f\, \delta t}\, df'. - \end{equation} - $$ - The right-hand side is just the inverse Fourier transform of $\tilde{g}(f')\, \tilde{h}^\ast(f')$, but this is easy and fast to compute! In this case, the inverse Fourier transform is a function of $\delta t$, so we can compute it, and then just pick the largest value, and we've automatically optimized the time offset. - - Now let's consider the rotation. If you dig down into the theory of gravitational waves, you'll find that they're actually best described as complex numbers — or more specifically, a gravitational wave is a complex-valued transverse wave. Our detectors just pick out one part of this complex field because it would cost about twice as much to pick out both parts. If you were to rotate the detector, you would also rotate the phase of the underlying complex field, but the detector would still just pick out one part — say, the real part. That is, the quantity $g$ above is actually the real part of some complex $G$, for which $G \mapsto e^{i\phi} G$. So, we have - $$ - \begin{equation} - g = \Re\{G\} \mapsto \Re\{e^{i\phi} G\} = g\cos\phi - g'\sin\phi, - \end{equation} - $$ - where $g'=\Im\{G\}$. - - So far in this section, we've been assuming that both signals $g$ and $h$ are already "equalized" by the noise spectrum. The squared noise spectrum is usually written $S_n(f)$. Using this, we define the "match" between two not-yet-equalized signals to be - $$ - \begin{aligned} - M(g, h) - &= \max_{\delta t}{}\ \int_{-\infty}^{\infty}\ g(t + \delta t)\, h(t)\, dt, \\ - &= \max_{\delta t}{}\ \int_{-\infty}^{\infty}\ \frac{\tilde{g}(f)\, \tilde{h}^\ast(f)} {S_n(f)}\, e^{2\pi\, i\, f\, \delta t}\, df. - \end{aligned} - $$ - The last form is just the inverse Fourier transform, and since the (inverse) FFT is such an efficient algorithm, it can be computed very quickly, and we just pick out the largest element of the result to get our answer. This is the actual formula that LIGO uses to run its searches. - """) - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - Now, to see how this works, we can apply it to the GW150914 data from above. We just take the Fourier-domain filtered detector data, multiply it by the Fourier-domain filtered simulated template signal (conjugated), and take the inverse FFT. The maximum value will tell us how much to offset the detector data to match the simulated signal as well as possible. - """) - return - - -@app.cell -def _( - h_filtered_tilde, - l_filtered_tilde, - np, - nr_filtered_h_tilde, - nr_filtered_l_tilde, -): - match_h = np.fft.irfft(h_filtered_tilde * nr_filtered_h_tilde.conjugate()) - match_l = np.fft.irfft(l_filtered_tilde * nr_filtered_l_tilde.conjugate()) - - optimal_offset_l = match_l.size-np.argmax(abs(match_l)) - optimal_offset_h = match_h.size-np.argmax(abs(match_h)) - - print("Index of the optimal Livingston offset:", optimal_offset_l) - print("Index of the optimal Hanford offset:", optimal_offset_h) - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - These are the origins of the mysterious 37 and 7 we used at the end of the previous section to get the best correlation between the data and the template signal. - """) - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - ## Questions - - * Can you derive the equation for the Fourier transform of a time-offset signal? - * Can you derive the equation for the correlation in the frequency domain? - * How can we normalize the input waveforms? - """) - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - # 8. More detections! - - Since the first detection, there have been several other detections and "triggers". A "trigger" is what LIGO calls an event that initially looks like a detection, but has not been evaluated in enough detail for them to be confident that it actually is an astrophysical phenomenon. - - You have been given some data of your own, containing data very similar to one of the four events that LIGO has identified so far. Your job is to find out which one. To make things a little easier on you, we first condense all of the fancy filtering and matching done above into a single function: - """) - return - - -@app.cell -def _(Latex, display, dt, fade, h5py, np, plt, sampling_rate, scipy, t): - def show_matches(h, l, nr, phase_offset=0.0): - - if isinstance(h, str): - with h5py.File(h) as f: - h = f['strain/Strain'][:] - htilde = dt * np.fft.rfft(h) - h_filtered = filter_signal(h, sampling_rate, upper_bandpass_frequency=512.0) - h_filtered_tilde = dt * np.fft.rfft(h_filtered) - - if isinstance(l, str): - with h5py.File(l) as f: - l = f['strain/Strain'][:] - ltilde = dt * np.fft.rfft(l) - l_filtered = filter_signal(l, sampling_rate, upper_bandpass_frequency=512.0) - l_filtered_tilde = dt * np.fft.rfft(l_filtered) - - if isinstance(nr, str): - with h5py.File(nr) as f: - nr = fade((np.exp(phase_offset) * (f['template'][0][:] + 1j*f['template'][1][:])).real) - nrtilde = dt * np.fft.rfft(nr) - nr_filtered_h = filter_signal(nr, sampling_rate, upper_bandpass_frequency=512.0, noisy_signal=h) - nr_filtered_h_tilde = dt * np.fft.rfft(nr_filtered_h) - nr_filtered_l = filter_signal(nr, sampling_rate, upper_bandpass_frequency=512.0, noisy_signal=l) - nr_filtered_l_tilde = dt * np.fft.rfft(nr_filtered_l) - - match_h = np.fft.irfft(h_filtered_tilde * nr_filtered_h_tilde.conjugate()) - match_l = np.fft.irfft(l_filtered_tilde * nr_filtered_l_tilde.conjugate()) - - optimal_offset_l = np.argmax(abs(match_l)) - optimal_offset_h = np.argmax(abs(match_h)) - - print("Index of the optimal Livingston offset:", optimal_offset_l) - print("Index of the optimal Hanford offset: ", optimal_offset_h) - - # Add small time offsets to the filtered detector data, to align the measured data to the model. - # (These precise offsets will be derived below.) - l_correlation = np.roll(l_filtered, -optimal_offset_l) * nr_filtered_l - h_correlation = np.roll(h_filtered, -optimal_offset_h) * nr_filtered_h - - # Integrate the correlation functions over time - c_l = scipy.integrate.simps(l_correlation, t) - c_h = scipy.integrate.simps(h_correlation, t) - display(Latex(r'$c_{{\mathrm{{Livingston}}}} = {0:.4f}$'.format(c_l))) - display(Latex(r'$c_{{\mathrm{{Hanford}}}} = {0:.4f}$'.format(c_h))) - - # Plot the correlation functions as functions of time - plt.close() - plt.figure() - plt.plot(t, np.sign(c_l)*l_correlation, label='Livingston') - plt.plot(t, np.sign(c_h)*h_correlation, label='Hanford') - plt.grid() - plt.xlim(15.75, 16.1) - plt.xlabel('Time (seconds)') - plt.ylabel('Correlation between data and simulated signal') - plt.legend() - plt.show(); - - - # You can use that function for any of the three events (or one trigger) with function calls like these: - #show_matches('data/H-H1_LOSC_4_V1-1126259446-32.hdf5', 'data/L-L1_LOSC_4_V1-1126259446-32.hdf5', 'data/GW150914_4_template.hdf5', 0.75j*np.pi) - #show_matches('data/H-H1_LOSC_4_V1-1128678884-32.hdf5', 'data/L-L1_LOSC_4_V1-1128678884-32.hdf5', 'data/LVT151012_4_template.hdf5', 0.024j*np.pi) - #show_matches('data/H-H1_LOSC_4_V1-1135136334-32.hdf5', 'data/L-L1_LOSC_4_V1-1135136334-32.hdf5', 'data/GW151226_4_template.hdf5', 0.0) - #show_matches('data/H-H1_LOSC_4_V1-1167559920-32.hdf5', 'data/L-L1_LOSC_4_V1-1167559920-32.hdf5', 'data/GW170104_4_template.hdf5', 0.08j*np.pi) - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - Now, retrieve your data: - """) - return - - -@app.cell -def _(): - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r""" - Figure out which of the four events best matches your data, and how it's not quite the same as the original LIGO event. - """) - return - - -@app.cell -def _(): - #your code goes here ... - return - - -@app.cell -def _(): - return - - -@app.cell -def _(): - return - - -@app.cell -def _(): - return - - -if __name__ == "__main__": - app.run() From d2a162903e5297f4ca5c1366208992abd56aa994 Mon Sep 17 00:00:00 2001 From: chengj7 <137737242+chengj7@users.noreply.github.com> Date: Thu, 15 Oct 2026 21:32:37 -0400 Subject: [PATCH 33/35] Refactor matchedfiltering.py for clarity and efficiency Updated notebook description and removed unused imports and functions. --- ...edfiltering_mpl.py => matchedfiltering.py} | 127 +----------------- 1 file changed, 2 insertions(+), 125 deletions(-) rename content/{_matchedfiltering_mpl.py => matchedfiltering.py} (90%) diff --git a/content/_matchedfiltering_mpl.py b/content/matchedfiltering.py similarity index 90% rename from content/_matchedfiltering_mpl.py rename to content/matchedfiltering.py index 8b026be..98c3123 100644 --- a/content/_matchedfiltering_mpl.py +++ b/content/matchedfiltering.py @@ -61,7 +61,7 @@ def _(mo): def _(mo): mo.md( r""" - This is a [Jupyter notebook](https://jupyter.org/) (formerly known as an [IPython notebook](http://ipython.org/notebook.html)). It's connected to an actual python session, but it runs through a web browser, so we can format things nicely and give some explanations, and so you don't have to copy-and-paste all the instructions into a normal python session. Plus, you can edit the code and explore the data interactively. It's meant to look and work kind of like Mathematica, if you've ever used that before. (And if you don't care for python, Jupyter also handles [Julia](http://nbviewer.ipython.org/url/jdj.mit.edu/~stevenj/IJulia%20Preview.ipynb), [R](https://github.com/IRkernel/IRkernel), [IDL](https://github.com/lstagner/idl_kernel), and numerous other languages.) + This is a [marimo notebook](https://marimo.io/). It's connected to an actual python session, but it runs through a web browser, so we can format things nicely and give some explanations, and so you don't have to copy-and-paste all the instructions into a normal python session. Plus, you can edit the code and explore the data interactively. It's meant to look and work kind of like Mathematica, if you've ever used that before. Each of the sections in gray with something like "`In[1]:`" in front of it is called a *cell* and contains code for you to run. Run the code by placing your cursor in the cell, then pressing Shift+Enter. @@ -96,10 +96,6 @@ def _(): import scipy.signal from scipy.interpolate import InterpolatedUnivariateSpline - # These are some nice interactive things we'll use in this notebook - #from IPython.display import display, Audio, Latex, clear_output - #import ipywidgets as widgets - # These are some messy functions I've defined in another file (`utilities.py`) import time @@ -119,7 +115,7 @@ def _(): sys.path.append(public_dir) - from utilities import (fade, derivative, plot_td_and_fd, plot_td_and_fd_edit, filter_and_plot, filter_and_plot_edit, + from utilities import (fade, derivative, plot_td_and_fd_edit, filter_and_plot_edit, add_notch_filter, filter_cheat, notch_data, bandpass, retrieve_new_data) @@ -1256,125 +1252,6 @@ def _(mo): return -@app.cell(hide_code=True) -def _(mo): - mo.md( - r""" - # 8. More detections! - - Since the first detection, there have been several other detections and "triggers". A "trigger" is what LIGO calls an event that initially looks like a detection, but has not been evaluated in enough detail for them to be confident that it actually is an astrophysical phenomenon. - - You have been given some data of your own, containing data very similar to one of the four events that LIGO has identified so far. Your job is to find out which one. To make things a little easier on you, we first condense all of the fancy filtering and matching done above into a single function: - """ - ) - return - - -@app.cell -def _(Latex, display, dt, fade, h5py, np, plt, sampling_rate, scipy, t): - def show_matches(h, l, nr, phase_offset=0.0): - - if isinstance(h, str): - with h5py.File(h) as f: - h = f['strain/Strain'][:] - htilde = dt * np.fft.rfft(h) - h_filtered = filter_signal(h, sampling_rate, upper_bandpass_frequency=512.0) - h_filtered_tilde = dt * np.fft.rfft(h_filtered) - - if isinstance(l, str): - with h5py.File(l) as f: - l = f['strain/Strain'][:] - ltilde = dt * np.fft.rfft(l) - l_filtered = filter_signal(l, sampling_rate, upper_bandpass_frequency=512.0) - l_filtered_tilde = dt * np.fft.rfft(l_filtered) - - if isinstance(nr, str): - with h5py.File(nr) as f: - nr = fade((np.exp(phase_offset) * (f['template'][0][:] + 1j*f['template'][1][:])).real) - nrtilde = dt * np.fft.rfft(nr) - nr_filtered_h = filter_signal(nr, sampling_rate, upper_bandpass_frequency=512.0, noisy_signal=h) - nr_filtered_h_tilde = dt * np.fft.rfft(nr_filtered_h) - nr_filtered_l = filter_signal(nr, sampling_rate, upper_bandpass_frequency=512.0, noisy_signal=l) - nr_filtered_l_tilde = dt * np.fft.rfft(nr_filtered_l) - - match_h = np.fft.irfft(h_filtered_tilde * nr_filtered_h_tilde.conjugate()) - match_l = np.fft.irfft(l_filtered_tilde * nr_filtered_l_tilde.conjugate()) - - optimal_offset_l = np.argmax(abs(match_l)) - optimal_offset_h = np.argmax(abs(match_h)) - - print("Index of the optimal Livingston offset:", optimal_offset_l) - print("Index of the optimal Hanford offset: ", optimal_offset_h) - - # Add small time offsets to the filtered detector data, to align the measured data to the model. - # (These precise offsets will be derived below.) - l_correlation = np.roll(l_filtered, -optimal_offset_l) * nr_filtered_l - h_correlation = np.roll(h_filtered, -optimal_offset_h) * nr_filtered_h - - # Integrate the correlation functions over time - c_l = scipy.integrate.simps(l_correlation, t) - c_h = scipy.integrate.simps(h_correlation, t) - display(Latex(r'$c_{{\mathrm{{Livingston}}}} = {0:.4f}$'.format(c_l))) - display(Latex(r'$c_{{\mathrm{{Hanford}}}} = {0:.4f}$'.format(c_h))) - - # Plot the correlation functions as functions of time - plt.close() - plt.figure() - plt.plot(t, np.sign(c_l)*l_correlation, label='Livingston') - plt.plot(t, np.sign(c_h)*h_correlation, label='Hanford') - plt.grid() - plt.xlim(15.75, 16.1) - plt.xlabel('Time (seconds)') - plt.ylabel('Correlation between data and simulated signal') - plt.legend() - plt.show(); - - - # You can use that function for any of the three events (or one trigger) with function calls like these: - #show_matches('data/H-H1_LOSC_4_V1-1126259446-32.hdf5', 'data/L-L1_LOSC_4_V1-1126259446-32.hdf5', 'data/GW150914_4_template.hdf5', 0.75j*np.pi) - #show_matches('data/H-H1_LOSC_4_V1-1128678884-32.hdf5', 'data/L-L1_LOSC_4_V1-1128678884-32.hdf5', 'data/LVT151012_4_template.hdf5', 0.024j*np.pi) - #show_matches('data/H-H1_LOSC_4_V1-1135136334-32.hdf5', 'data/L-L1_LOSC_4_V1-1135136334-32.hdf5', 'data/GW151226_4_template.hdf5', 0.0) - #show_matches('data/H-H1_LOSC_4_V1-1167559920-32.hdf5', 'data/L-L1_LOSC_4_V1-1167559920-32.hdf5', 'data/GW170104_4_template.hdf5', 0.08j*np.pi) - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r"""Now, retrieve your data:""") - return - - -@app.cell -def _(): - return - - -@app.cell(hide_code=True) -def _(mo): - mo.md(r"""Figure out which of the four events best matches your data, and how it's not quite the same as the original LIGO event.""") - return - - -@app.cell -def _(): - #your code goes here ... - return - - -@app.cell -def _(): - return - - -@app.cell -def _(): - return - - -@app.cell -def _(): - return - if __name__ == "__main__": app.run() From 420137ac9a6f6f0938ea40620b77044ad38d5933 Mon Sep 17 00:00:00 2001 From: chengj7 <137737242+chengj7@users.noreply.github.com> Date: Thu, 15 Oct 2026 21:39:05 -0400 Subject: [PATCH 34/35] Update script paths in pyproject.toml --- pyproject.toml | 13 ++++--------- 1 file changed, 4 insertions(+), 9 deletions(-) diff --git a/pyproject.toml b/pyproject.toml index 9fac5bf..f2c172e 100644 --- a/pyproject.toml +++ b/pyproject.toml @@ -3,13 +3,11 @@ # version. This isn't actually a project, and we're not tracking the # project's version. [project] -name = "plots.matched-filtering.org" version = "1.0.0" requires-python = ">=3.13,<3.14" # Ditto the fakery here. This just lets marimo run [tool.setuptools.packages.find] -include = ["plots"] exclude = ["document_root*"] [tool.hatch.envs.marimo] @@ -18,12 +16,9 @@ extra-dependencies = [ "uv", ] -[tool.marimo.runtime] -output_max_bytes = 8_500_000 - [tool.hatch.envs.marimo.scripts] config-check = "marimo config show" -edit = "marimo edit --sandbox ./content/_matchedfiltering_mpl.py" -run = "marimo run --sandbox ./content/_matchedfiltering_mpl.py" -check = "uv run ./content/_matchedfiltering_mpl.py" # Just to see if the script runs successfully -convert = "marimo export html-wasm ./content/_matchedfiltering_mpl.py -f -o output/ --mode edit" +edit = "marimo edit --sandbox ./content/matchedfiltering.py" +run = "marimo run --sandbox ./content/matchedfiltering.py" +check = "uv run ./content/matchedfiltering.py" # Just to see if the script runs successfully +convert = "marimo export html-wasm ./content/matchedfiltering.py -f -o output/ --mode edit" From 1fe2a887d2ec6647dd3b80a0802c9582fb6ad982 Mon Sep 17 00:00:00 2001 From: chengj7 <137737242+chengj7@users.noreply.github.com> Date: Thu, 15 Oct 2026 23:17:24 -0400 Subject: [PATCH 35/35] Add project name and version to pyproject.toml --- pyproject.toml | 1 + 1 file changed, 1 insertion(+) diff --git a/pyproject.toml b/pyproject.toml index f2c172e..18fa795 100644 --- a/pyproject.toml +++ b/pyproject.toml @@ -3,6 +3,7 @@ # version. This isn't actually a project, and we're not tracking the # project's version. [project] +name = "plots.matched-filtering.org" version = "1.0.0" requires-python = ">=3.13,<3.14"